# POST: Create a New Stem Splitter Job
Source: https://docs.kits.ai/api-reference/api-endpoints/stem-splitter-api/create-new-stem-splitter-job
POST https://arpeggi.io/api/kits/v1/stem-splits
Create a new job to split vocals and instruments from audio tracks using the Kits API.
Creates a [stem splitter job](/api-reference/types-limits/vocal-separation-job) and adds it to the splitter queue. All requests must be made as multipart form requests. The response will contain the job status.
### Headers
Bearer (api-key)
### Request Body
Supports wav, webm, mp3 or flac. Max file size is 50MB.
### Response
[Stem Splitter Job](/api-reference/types-limits/vocal-separation-job)
```bash cURL theme={null}
curl -X POST https://arpeggi.io/api/kits/v1/stem-splits \
-H "Authorization: Bearer your_api_key" \
-F "inputFile=@file_path"
```
```python Python theme={null}
url = "https://arpeggi.io/api/kits/v1/stem-splits"
files = { 'inputFile': open(file_path, 'rb') }
headers = { 'Authorization': f'Bearer {your_api_key}' }
response = requests.post(url, files=files, headers=headers)
stem_splitter_job = response.json()
```
```javascript JavaScript theme={null}
const url = 'https://arpeggi.io/api/kits/v1/stem-splits'
const data = { inputFile: fs.createReadStream(file_path) }
const headers = { Authorization: `Bearer ${your_api_key}` }
const response = await axios.postForm(url, data, { headers })
const stemSplitterJob = response.data
```
```json 200: OK theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": null,
"vocalAudioFileUrl": null,
"lossyVocalAudioFileUrl": null,
"backingAudioFileUrl": null,
"stemFileUrls": [],
"lossyStemFileUrls": []
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Request body is invalid.
```
```bash 429: Too Many Requests theme={null}
Rate limit exceeded.
```
# GET: Fetch a Stem Splitter Job by ID
Source: https://docs.kits.ai/api-reference/api-endpoints/stem-splitter-api/fetch-stem-splitter-job-by-id
GET https://arpeggi.io/api/kits/v1/stem-splits/:id
Get specific stem splitter jobs by ID with the Kits API.
Returns a single [stem splitter job](/api-reference/types-limits/vocal-separation-job) by id.
### Headers
Bearer ``
### Response
[Stem Splitter Job](/api-reference/types-limits/vocal-separation-job)
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```json 200: OK theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": "2023-09-19 20:16:45.227000 +00:00",
"vocalAudioFileUrl": "https://...",
"lossyVocalAudioFileUrl": "https://...",
"backingAudioFileUrl": "https://...",
"stemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
],
"lossyStemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
]
}
```
```bash 403: Forbidden theme={null}
Attempted to fetch a job that does not belong to the requesting user.
```
```bash 404: Not Found theme={null}
```
# GET: Fetch Stem Splitter Jobs
Source: https://docs.kits.ai/api-reference/api-endpoints/stem-splitter-api/fetch-stem-splitter-jobs
GET https://arpeggi.io/api/kits/v1/stem-splits
Get statuses of stem splitter jobs using the Kits API.
Returns a paginated list of [stem splitter jobs](/api-reference/types-limits/vocal-separation-job).
### Query Parameters
asc (default) or desc
Page offset (default 1)
Page size (default 10)
### Headers
Bearer (api-key)
### Response
[Stem Splitter Job](/api-reference/types-limits/vocal-separation-job)
[Pagination Meta](/api-reference/types-limits/pagination-meta)
```json 200: OK Paginated stem splitter jobs theme={null}
{
"data": [
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": "2023-09-19 20:16:45.227000 +00:00",
"vocalAudioFileUrl": "https://...",
"lossyVocalAudioFileUrl": "https://...",
"backingAudioFileUrl": "https://...",
"stemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
],
"lossyStemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
]
},
...
],
"meta": {
"currentPage": 1,
"firstPage": 1,
"firstPageUrl": "/?page=1",
"lastPage": 3,
"lastPageUrl": "/?page=2",
"nextPageUrl": "/?page=3",
"perPage": 10,
"previousPageUrl": null,
"total": 30,
}
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Query params are invalid.
```
# POST: Create a New Vocal Separation Job
Source: https://docs.kits.ai/api-reference/api-endpoints/vocal-separations-api/create-new-vocal-separation-job
POST https://arpeggi.io/api/kits/v1/vocal-separations
Create a new job to isolate vocals from audio tracks using the Kits API.
Creates a [vocal separation job](/api-reference/types-limits/vocal-separation-job) and adds it to the separator queue. All requests must be made as multipart form requests. The response will contain the job status.
### Headers
Bearer (api-key)
### Request Body
Supports wav, webm, mp3 or flac. Max file size is 50MB.
### Response
[Vocal Separation Job](/api-reference/types-limits/vocal-separation-job)
```bash cURL theme={null}
curl -X POST https://arpeggi.io/api/kits/v1/vocal-separations \
-H "Authorization: Bearer your_api_key" \
-F "inputFile=@file_path"
```
```python Python theme={null}
url = "https://arpeggi.io/api/kits/v1/vocal-separations"
files = { 'inputFile': open(file_path, 'rb') }
headers = { 'Authorization': f'Bearer {your_api_key}' }
response = requests.post(url, files=files, headers=headers)
vocal_separation_job = response.json()
```
```javascript JavaScript theme={null}
const url = 'https://arpeggi.io/api/kits/v1/vocal-separations'
const data = { inputFile: fs.createReadStream(file_path) }
const headers = { Authorization: `Bearer ${your_api_key}` }
const response = await axios.postForm(url, data, { headers })
const vocalSeparationJob = response.data
```
```json 200: OK theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": null,
"vocalAudioFileUrl": null,
"lossyVocalAudioFileUrl": null,
"backingAudioFileUrl": null,
"stemFileUrls": [],
"lossyStemFileUrls": []
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Request body is invalid.
```
```bash 429: Too Many Requests theme={null}
Rate limit exceeded.
```
# GET: Fetch a Vocal Separation Job by ID
Source: https://docs.kits.ai/api-reference/api-endpoints/vocal-separations-api/fetch-vocal-separation-job-by-id
GET https://arpeggi.io/api/kits/v1/vocal-separations/:id
Get specific vocal separation jobs by ID with the Kits API.
Returns a single [vocal separation job](/api-reference/types-limits/vocal-separation-job) by id.
### Headers
Bearer ``
### Response
[Vocal Separation Job](/api-reference/types-limits/vocal-separation-job)
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```json 200: OK theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": "2023-09-19 20:16:45.227000 +00:00",
"vocalAudioFileUrl": "https://...",
"lossyVocalAudioFileUrl": "https://...",
"backingAudioFileUrl": "https://...",
"stemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
],
"lossyStemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
]
}
```
```bash 403: Forbidden theme={null}
Attempted to fetch a job that does not belong to the requesting user.
```
```bash 404: Not Found theme={null}
```
# GET: Fetch Vocal Separation Jobs
Source: https://docs.kits.ai/api-reference/api-endpoints/vocal-separations-api/fetch-vocal-separation-jobs
GET https://arpeggi.io/api/kits/v1/vocal-separations
Get statuses of vocal separation jobs using the Kits API.
Returns a paginated list of [vocal separation jobs](/api-reference/types-limits/vocal-separation-job).
### Query Parameters
asc (default) or desc
Page offset (default 1)
Page size (default 10)
### Headers
Bearer (api-key)
### Response
[Vocal Separation Job](/api-reference/types-limits/vocal-separation-job)
[Pagination Meta](/api-reference/types-limits/pagination-meta)
```json 200: OK Paginated vocal separation jobs theme={null}
{
"data": [
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "separate",
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": "2023-09-19 20:16:45.227000 +00:00",
"vocalAudioFileUrl": "https://...",
"lossyVocalAudioFileUrl": "https://...",
"backingAudioFileUrl": "https://...",
"stemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
],
"lossyStemFileUrls": [
{ "instrument": "vocals", "url": "https://..." },
{ "instrument": "harmony", "url": "https://..." },
{ "instrument": "reverb", "url": "https://..." }
]
},
...
],
"meta": {
"currentPage": 1,
"firstPage": 1,
"firstPageUrl": "/?page=1",
"lastPage": 3,
"lastPageUrl": "/?page=2",
"nextPageUrl": "/?page=3",
"perPage": 10,
"previousPageUrl": null,
"total": 30,
}
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Query params are invalid.
```
# POST: Create a Voice Blender Job
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-blender-api/create-new-voice-blender-job
POST https://arpeggi.io/api/kits/v1/voice-blender
Create a new job to blend multiple voices using the Kits API.
Creates a [voice blender job](/api-reference/types-limits/vocal-blender-job) and adds it to the blender queue. The response will contain the job status along with the id of the output voice model. Note that the output model will only be usable once the job has status "success".
When creating voice blender jobs, you need to provide at least two voice models to blend, but can provide up to four. You'll also need to provider one less alpha value than the number of voice models you're blending, as the last alpha value is calculated automatically as 1 - the sum of the other alpha values.
### Headers
Bearer (api-key)
### Request Body
The id of the first voice model to blend.
The id of the second voice model to blend.
The id of the third voice model to blend.
The id of the fourth voice model to blend.
The percentage of the output model that will be the first voice model. Range from 0 to 1.
If three or more models are provided, this indicates the percentage of the output model that will be the second voice model. Required if modelId3 is provided. Range from 0 to 1.
If four or more models are provided, this indicates the percentage of the output model that will be the third voice model. Required if modelId4 is provided. Range from 0 to 1.
The title of the new voice model.
### Response
[Voice Blender Job](/api-reference/types-limits/vocal-blender-job)
```bash cURL theme={null}
curl -X POST "https://arpeggi.io/api/kits/v1/voice-blender" \
-H "Authorization: Bearer YOUR_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"modelId1": 6,
"modelId2": 15,
"modelId3": 83,
"alpha": 0.33,
"alpha2": 0.33,
"title": "My New Voice Model"
}'
```
```python Python theme={null}
url = "https://arpeggi.io/api/kits/v1/voice-blender"
headers = { 'Authorization': f'Bearer {your_api_key}' }
data = { modelId1: 6, modelId2: 15, modelId3: 83, alpha: 0.33, alpha2: 0.33, title: "My New Voice Model" }
response = requests.post(url, data=data, headers=headers)
voice_blender_job = response.json()
```
```javascript JavaScript theme={null}
const url = 'https://arpeggi.io/api/kits/v1/voice-blender'
const headers = { Authorization: `Bearer ${your_api_key}` }
const data = (data = {
modelId1: 6,
modelId2: 15,
modelId3: 83,
alpha: 0.33,
alpha2: 0.33,
title: 'My New Voice Model'
})
const response = await axios.post(url, data, { headers })
const voiceBlenderJob = response.data
```
```json 200: OK theme={null}
{
"id": 110784,
"model1Id": 6,
"model2Id": 15,
"model3Id": 83,
"alpha": 0.33,
"alpha2": 0.33,
"alpha3": 0.34,
"status": "running",
"outputModelId": 600,
"title": "My New Voice Model"
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Request body is invalid.
```
```bash 429: Too Many Requests theme={null}
Rate limit exceeded.
```
# GET: Fetch a Voice Blender Job by ID
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-blender-api/fetch-voice-blender-job-by-id
GET https://arpeggi.io/api/kits/v1/voice-blender/:id
Get specific voice blender job by ID using the Kits API.
Returns a single [voice blender job](/api-reference/types-limits/voice-blender-job) by id.
### Headers
Bearer ``
### Response
[Voice Blender Job](/api-reference/types-limits/voice-blender-job)
```json 200: OK theme={null}
{
"id": 110784,
"model1Id": 501,
"model2Id": 234,
"model3Id": 53,
"model4Id": 90,
"alpha": 0.1,
"alpha2": 0.3,
"alpha3": 0.4,
"alpha4": 0.2,
"status": "success",
"outputModelId": 600
}
```
```bash 404: Not Found theme={null}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 403: Forbidden theme={null}
Attempted to fetch a voice blender job that does not belong to the requesting user.
```
# GET: Fetch Voice Blender Jobs
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-blender-api/fetch-voice-blender-jobs
GET https://arpeggi.io/api/kits/v1/voice-blender
Retrieve statuses of voice blender jobs with the Kits API.
Returns a paginated list of [voice blender jobs](/api-reference/types-limits/voice-blender-job).
### Query Parameters
asc (default) or desc
Page offset (default 1)
Page size (default 50)
### Headers
Bearer ``
### Response
[Voice Blender Job](/api-reference/types-limits/voice-blender-job)
[Pagination Meta](/api-reference/types-limits/pagination-meta)
```json 200: OK Paginated voice blender jobs theme={null}
{
"data": [
{
"id": 110784,
"model1Id": 501,
"model2Id": 234,
"model3Id": 53,
"model4Id": 90,
"alpha": 0.1,
"alpha2": 0.3,
"alpha3": 0.4,
"alpha4": 0.2,
"status": "success",
"outputModelId": 600
},
...
],
"meta": {
"currentPage": 1,
"firstPage": 1,
"firstPageUrl": "/?page=1",
"lastPage": 3,
"lastPageUrl": "/?page=2",
"nextPageUrl": "/?page=3",
"perPage": 10,
"previousPageUrl": null,
"total": 30,
}
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 403: Forbidden theme={null}
Attempted to fetch a job that does not belong to the requesting user.
```
```bash 429: Too many requests theme={null}
Rate limit exceeded.
```
# POST: Create a New Voice Conversion Job
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-conversion-api/create-new-voice-conversion-job
POST https://arpeggi.io/api/kits/v1/voice-conversions
Create a job to convert one voice to another with the Kits API.
Creates a voice conversion [inference job](/api-reference/types-limits/inference-job) and adds it to the inference queue. All requests must be made as multipart form requests. The response will contain the job status.
### Headers
Bearer ``
### Request Body
ID of the voice model.
Supports wav, mp3, or flac. Max file size is 100MB.
Increases the amount of accent from the Voice Model. This may cause mispronunciation. Range from 0 to 1.
Increase to convert the volume of your input audio to the volume of the AI model. Decrease to hear dynamics from the input audio. High values may accentuate noise. Range from 0 to 1.
The number of semitones to shift the input audio. Range from -24 to 24.
[Preprocessing effects](/api-reference/types-limits/pre-processing-effects) run on the input file before the conversion is processed.
[Postprocessing effects](/api-reference/types-limits/post-processing-effects) run on the output file after the conversion is processed.
### Response
[Inference Job](/api-reference/types-limits/inference-job)
```bash cURL theme={null}
curl -X POST https://arpeggi.io/api/kits/v1/voice-conversions \
-H "Authorization: Bearer your_api_key" \
-F "voiceModelId=voice_model_id" \
-F "soundFile=@file_path"
```
```python Python theme={null}
url = "https://arpeggi.io/api/kits/v1/voice-conversions"
data = { 'voiceModelId': voice_model_id }
files = { 'soundFile': open(file_path, 'rb') }
headers = { 'Authorization': f'Bearer {your_api_key}' }
response = requests.post(url, data=data, files=files, headers=headers)
vocal_conversion_job = response.json()
```
```javascript JavaScript theme={null}
const url = 'https://arpeggi.io/api/kits/v1/voice-conversions'
const data = {
voiceModelId: voice_model_id,
soundFile: fs.createReadStream(file_path)
}
const headers = { Authorization: `Bearer ${your_api_key}` }
const response = await axios.postForm(url, data, { headers })
const vocalConversionJob = response.data
```
```json 201: Created theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "infer",
"voiceModelId": 2,
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": null
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 422: Unprocessable Entity theme={null}
Request body is invalid.
```
```bash 429: Too many requests theme={null}
Rate limit exceeded.
```
# GET: Fetch a Voice Conversion by ID
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-conversion-api/fetch-conversion-by-id
GET https://arpeggi.io/api/kits/v1/voice-conversions/:id
Get specific voice conversion jobs by ID with the Kits API.
Returns a single voice conversion [inference job](/api-reference/types-limits/inference-job) by id.
### Headers
Bearer ``
### Response
[Inference Job](/api-reference/types-limits/inference-job)
```json 200: OK theme={null}
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "infer",
"voiceModelId": 2,
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": null
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 403: Forbidden theme={null}
Attempted to fetch a job that does not belong to the requesting user.
```
```bash 429: Too many requests theme={null}
Rate limit exceeded.
```
# GET: Fetch Voice Conversions
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-conversion-api/fetch-voice-conversions
GET https://arpeggi.io/api/kits/v1/voice-conversions
Retrieve statuses of voice conversion jobs with the Kits API.
Returns a paginated list of voice conversion [inference jobs](/api-reference/types-limits/inference-job).
### Query Parameters
asc (default) or desc
Page offset (default 1)
Page size (default 10)
### Headers
Bearer ``
### Response
[Inference Job](/api-reference/types-limits/inference-job)
[Pagination Meta](/api-reference/types-limits/pagination-meta)
```json 200: OK Paginated inference jobs theme={null}
{
"data": [
{
"id": 1,
"createdAt": "2023-09-19 20:13:50.428000 +00:00",
"type": "infer",
"voiceModelId": 1,
"status": "running",
"jobStartTime": "2023-09-19 20:15:50.428000 +00:00",
"jobEndTime": null
},
...
],
"meta": {
"currentPage": 1,
"firstPage": 1,
"firstPageUrl": "/?page=1",
"lastPage": 3,
"lastPageUrl": "/?page=2",
"nextPageUrl": "/?page=3",
"perPage": 10,
"previousPageUrl": null,
"total": 30,
}
}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 403: Forbidden theme={null}
Attempted to fetch a job that does not belong to the requesting user.
```
```bash 429: Too many requests theme={null}
Rate limit exceeded.
```
# GET: Fetch Voice Models
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-model-api/fetch-voice-models
GET https://arpeggi.io/api/kits/v1/voice-models
Access available voice models using the Kits API.
Returns a paginated list of [voice models](/api-reference/types-limits/voice-model).
### Query Parameters
asc (default) or desc
Page offset (default 1)
Page size (default 10)
Filter the response to your models only.
Filter the response to instrument models only.
### Headers
Bearer ``
### Response
[Voice Model](/api-reference/types-limits/voice-model)
[Pagination Meta](/api-reference/types-limits/pagination-meta)
```json 200: OK theme={null}
{
"data": [
{
"id": 110784,
"title": "Male Pop",
"tags": ["Singing", "Chest Voice", "Classical", "Opera", "Jazz"],
"imageUrl": "https://arpeggi-prod-public.s3.us-west-2.amazonaws.com/voice-models/images/WOPD47ciycl4AkcXyxiwT.png",
"demoUrl": "https://arpeggi-prod-public.s3.us-west-2.amazonaws.com/voice-models/demos/tszZHHKzsrbXMiVfz7irs.mp3",
"twitterLink": null,
"instagramLink": null,
"tiktokLink": null,
"spotifyLink": null,
"youtubeLink": null
},
...
],
"meta": {
"currentPage": 1,
"firstPage": 1,
"firstPageUrl": "/?page=1",
"lastPage": 3,
"lastPageUrl": "/?page=2",
"nextPageUrl": "/?page=3",
"perPage": 10,
"previousPageUrl": null,
"total": 30,
}
}
```
```bash 422: Unprocessable Entity theme={null}
Query params are invalid.
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
# GET: Fetch a Voice Models by ID
Source: https://docs.kits.ai/api-reference/api-endpoints/voice-model-api/fetch-voice-models-by-id
GET https://arpeggi.io/api/kits/v1/voice-models/:id
Get specific voice models by ID using the Kits API.
Returns a single [voice model](/api-reference/types-limits/voice-model) by id.
### Headers
Bearer ``
### Response
[Voice Model](/api-reference/types-limits/voice-model)
```json 200: OK theme={null}
{
"id": 110784,
"title": "Male Pop",
"tags": ["Singing", "Chest Voice", "Classical", "Opera", "Jazz"],
"imageUrl": "https://arpeggi-prod-public.s3.us-west-2.amazonaws.com/voice-models/images/WOPD47ciycl4AkcXyxiwT.png",
"demoUrl": "https://arpeggi-prod-public.s3.us-west-2.amazonaws.com/voice-models/demos/tszZHHKzsrbXMiVfz7irs.mp3",
"twitterLink": null,
"instagramLink": null,
"tiktokLink": null,
"spotifyLink": null,
"youtubeLink": null
}
```
```bash 404: Not Found theme={null}
```
```bash 401: Unauthorized theme={null}
Authentication was not provided or was invalid.
```
```bash 403: Forbidden theme={null}
Attempted to fetch a model that is non-public or does not belong to the requesting user.
```
# Creating an API Key
Source: https://docs.kits.ai/api-reference/introduction/getting-started
Learn how to start using the Kits API with basic setup and authentication.
To create an API Key, head to our [API Access Page](https://app.kits.ai/api-access) and generate a new token.
Once you have an API key, this key must be sent in the headers of each request you send, as outlined in the documentation.
[For tips on getting setup and using the Kits API, check out our video tutorial](https://youtu.be/DBtw2B88BsQ?si=VOCwAzsawRimUhIg\&t=540).
If you need to increase your rate limits, [please fill out this form](https://help.kits.ai/hc/en-us/requests/new).
# Quick Start
Source: https://docs.kits.ai/api-reference/introduction/quick-start
Learn how to quickly get going using the Kits AI Vocal Conversion API.
Once you've generated an [API key](/api-reference/types-limits/getting-started), you can now make your first request to the Kits API.
All of the POST requests to create new jobs require multipart form requests, so this format can be applied to all of our POST requests, but we'll use the [convert audio](/api-reference/api-endpoints/voice-conversion-api/create-new-voice-conversion-job) endpoint as an example using the Female LoFi Royalty-Free voice model.
```bash cURL theme={null}
curl -X POST https://arpeggi.io/api/kits/v1/voice-conversions \
-H "Authorization: Bearer your_api_key" \
-F "voiceModelId=1014961" \
-F "soundFile=@file_path"
```
```python Python theme={null}
url = "https://arpeggi.io/api/kits/v1/voice-conversions"
data = { 'voiceModelId': 1014961 } # Female LoFi
files = { 'soundFile': open(file_path, 'rb') }
headers = { 'Authorization': f'Bearer {your_api_key}' }
response = requests.post(url, data=data, files=files, headers=headers)
vocal_conversion_job = response.json()
```
```javascript JavaScript theme={null}
const url = 'https://arpeggi.io/api/kits/v1/voice-conversions'
const data = {
voiceModelId: 1014961, // Female LoFi
soundFile: fs.createReadStream(file_path)
}
const headers = { Authorization: `Bearer ${your_api_key}` }
const response = await axios.postForm(url, data, { headers })
const vocalConversionJob = response.data
```
# Inference Job
Source: https://docs.kits.ai/api-reference/types-limits/inference-job
Represents an inference job that has been created through the API.
## Attributes
`id:` **number**
Unique identifier for the job.
`createdAt:` **string**
Creation time of the job.
`type:` **'infer' | 'tts'**
The type of inference job.
`status:` **'running' | 'success' | 'error' | 'cancelled'**
Current status of the job.
`jobStartTime:` **string | null**
Time that job was started.
`jobEndTime:` **string | null**
Time that the job ended.
`outputFileUrl:` **string | null**
Signed URL for the job's output file (expires in 4 hours).
`lossyOutputFileUrl:` **string | null**
Signed URL for the lossy version of the job's output file (expires in 4 hours).
`recombinedAudioFileUrl:` **string | null**
Signed URL for the job's recombined audio file (expires in 4 hours).
`voiceModelId:` **string | null | undefined**
ID of the associated Voice Model.
`model:` **VoiceModel** **| null**
The associated Voice Model.
# Paginated Response
Source: https://docs.kits.ai/api-reference/types-limits/paginated-response
All list endpoints will return a paginated response of this form.
## Attributes
`data:` T\[]
An array of data for the pages requested.
`meta:` [`PaginationMeta`](/api-reference/types-limits/pagination-meta)
Pagination metadata for the current request.
# Pagination Meta
Source: https://docs.kits.ai/api-reference/types-limits/pagination-meta
Meta properties on each paginated request.
## Attributes
`total:` **number**
Total number of results.
`perPage:` **number**
Total number of entries per page.
`currentPage:` **number**
The current page of pagination.
`lastPage:` **number**
The last page of pagination.
`firstPage:` **number**
The first page of pagination.
`firstPageUrl:` **string**
Url to the first page of pagination.
`lastPageUrl:` **string**
Url to the last page of pagination.
`nextPageUrl:` **string | null**
Url to the next page of pagination.
`previousPageUrl:` **string | null**
Url to the previous page of pagination.
# PostProcessingEffects
Source: https://docs.kits.ai/api-reference/types-limits/post-processing-effects
Explore post-processing effects in the Kits API for better audio processing.
`Chorus:` **object**
```
{
rate_hz: number (0 to 100);
depth: number (>= 0);
centre_delay_ms: number (>= 0);
feedback: number (>= 0);
mix: number (>= 0);
}
```
`Reverb:` **object**
```
{
room_size: number (0 to 1);
damping: number (0 to 1);
wet_level: number (0 to 1);
dry_level: number (0 to 1);
width: number (>= 0);
freeze_mode: number (>= 0);
}
```
`Compressor:` **object**
```
{
threshold_db: number;
ratio: number (>= 0);
attack_ms: number (>= 0);
release_ms: number (>= 0);
}
```
`Delay:` **object**
```
{
delay_seconds: number (>= 0);
feedback: number (>= 0);
mix: number (0 to 1);
}
```
# PreProcessingEffects
Source: https://docs.kits.ai/api-reference/types-limits/pre-processing-effects
Explore pre-processing effects in the Kits API for better audio processing.
`NoiseGate:` **object**
```
{
threshold_db: number
ratio: number (> 0);
attack_ms: number (>= 0);
release_ms: number (>= 0);
}
```
`HighPassFilter:` **object**
```
{
cutoff_frequency_hz: number (0 to 99999);
}
```
`LowPassFilter:` **object**
```
{
cutoff_frequency_hz: number (0 to 99999);
}
```
`Compressor:` **object**
```
{
threshold_db: number;
ratio: number (>= 0);
attack_ms: number (>= 0);
release_ms: number (>= 0);
}
```
# Rate Limits
Source: https://docs.kits.ai/api-reference/types-limits/rate-limits
Learn about rate limits for using the Kits API.
Current rate limits are set at 1000 `GET` requests per user each minute and 1 `POST` requests per user each minute for POST requests.
Rate limits are subject to change after our Alpha period.
Users with multiple API keys should be aware that rate limiting is tied to their Kits.AI account, not the individual API key. Therefore, all requests from the keys on your account will be attributed to your usage.
# Vocal Separation Job
Source: https://docs.kits.ai/api-reference/types-limits/vocal-separation-job
Represents a vocal separation job that has been created through the API.
## Attributes
`id:` **number**
Unique identifier for the job.
`createdAt:` **string**
Creation time of the job.
`type:` **'separate'**
The type of inference job.
`status:` **'running' | 'success' | 'error' | 'cancelled'**
Current status of the job.
`jobStartTime:` **string | null**
Time that job was started.
`jobEndTime:` **string | null**
Time that the job ended.
`vocalAudioFileUrl:` **string | null**
Signed URL for the job's vocal output file (expires in 4 hours).
`lossyVocalAudioFileUrl:` **string | null**
Signed URL for the job's lossy vocal output file (expires in 4 hours).
`DEPRECATED: backingAudioFileUrl:` **string | null**
Signed URL for the job's backing output file (expires in 4 hours). NOTE: use stemFileUrls or lossyStemFileUrls with instrument "backing" instead.
`stemFileUrls:` **\{ instrument: string; url: string }\[] | null**
Array of dictionaries for each instrument in the separator job, where "instrument" is the name of the instrument and url is a signed URL for that instrument's output file (expires in 4 hours).
`lossyStemFileUrls:` **\{ instrument: string; url: string }\[] | null**
Array of dictionaries for each instrument in the separator job, where "instrument" is the name of the instrument and url is a signed URL for that instrument's lossy output file (expires in 4 hours).
# Voice Blender Job
Source: https://docs.kits.ai/api-reference/types-limits/voice-blender-job
Represents a voice blender job created by the user. These jobs take between 2 and 4 voice models, and blends them given a set of alpha values that represent the percent the output voice model is comprised of each input voice model. Once the job has status "success", the output voice model will be usable just like any other voice model.
## Attributes
`id:` **number**
Unique identifier for the model.
`title:` **string**
Title of the voice model.
`status:` **'running' | 'success' | 'error' | 'cancelled'**
Status of the voice blender job. The `outputModelId` model will only be usable once the job has status "success".
`outputModelId:` **number**
ID of the output [voice model](/api-reference/types-limits/voice-model).
`model1Id:` **number**
ID of the first voice model.
`model2Id:` **number**
ID of the second voice model.
`model3Id:` **number | null**
ID of the third voice model.
`model4Id:` **number | null**
ID of the fourth voice model.
`alpha:` **number**
Percentage of the output voice model that is comprised of the voice model with ID `model1Id`.
`alpha2:` **number**
Percentage of the output voice model that is comprised of the voice model with ID `model2Id`.
`alpha3:` **number | null**
Percentage of the output voice model that is comprised of the voice model with ID `model3Id`.
`alpha4:` **number | null**
Percentage of the output voice model that is comprised of the voice model with ID `model4Id`.
# Voice Model
Source: https://docs.kits.ai/api-reference/types-limits/voice-model
Represents a voice model that may be user created or internal to Kits.ai.
## Attributes
`id:` **number**
Unique identifier for the model.
`title:` **string**
Title of the voice model.
`isUsable:` **boolean**
Whether the model is usable for inference or not. Unusable models are generally either currently training or blending, so this should only ever be false temporarily.
`tags:` **string\[] | null**
Related tags to improve searchability.
`imageUrl:` **string | null**
Public S3 url to the voice model image.
`demoUrl:` **string | null**
Public S3 url to the demo audio.
`twitterLink:` **string | null**
Twitter link defined for the model\*\*.\*\*
`instagramLink:` **string | null**
Instagram link defined for the model.
`tiktokLink:` **string | null**
TikTok link defined for the model.
`spotifyLink:` **string | null**
Spotify link defined for the model.
`youtubeLink:` **string | null**
YouTube link defined for the model.
# Step 1: Connect your Stripe account
Source: https://docs.kits.ai/earn/connect-your-stripe
Instructions for connecting your Stripe account to submit your trained voice and earn payouts.
In order to receive payouts, you must register your Stripe Connect account, which enables us to pay you in a timely manner and stay compliant.
To register with Stripe, log in to Kits and go to the [Earn page](https://app.kits.ai/earn) and select "Connect Account"
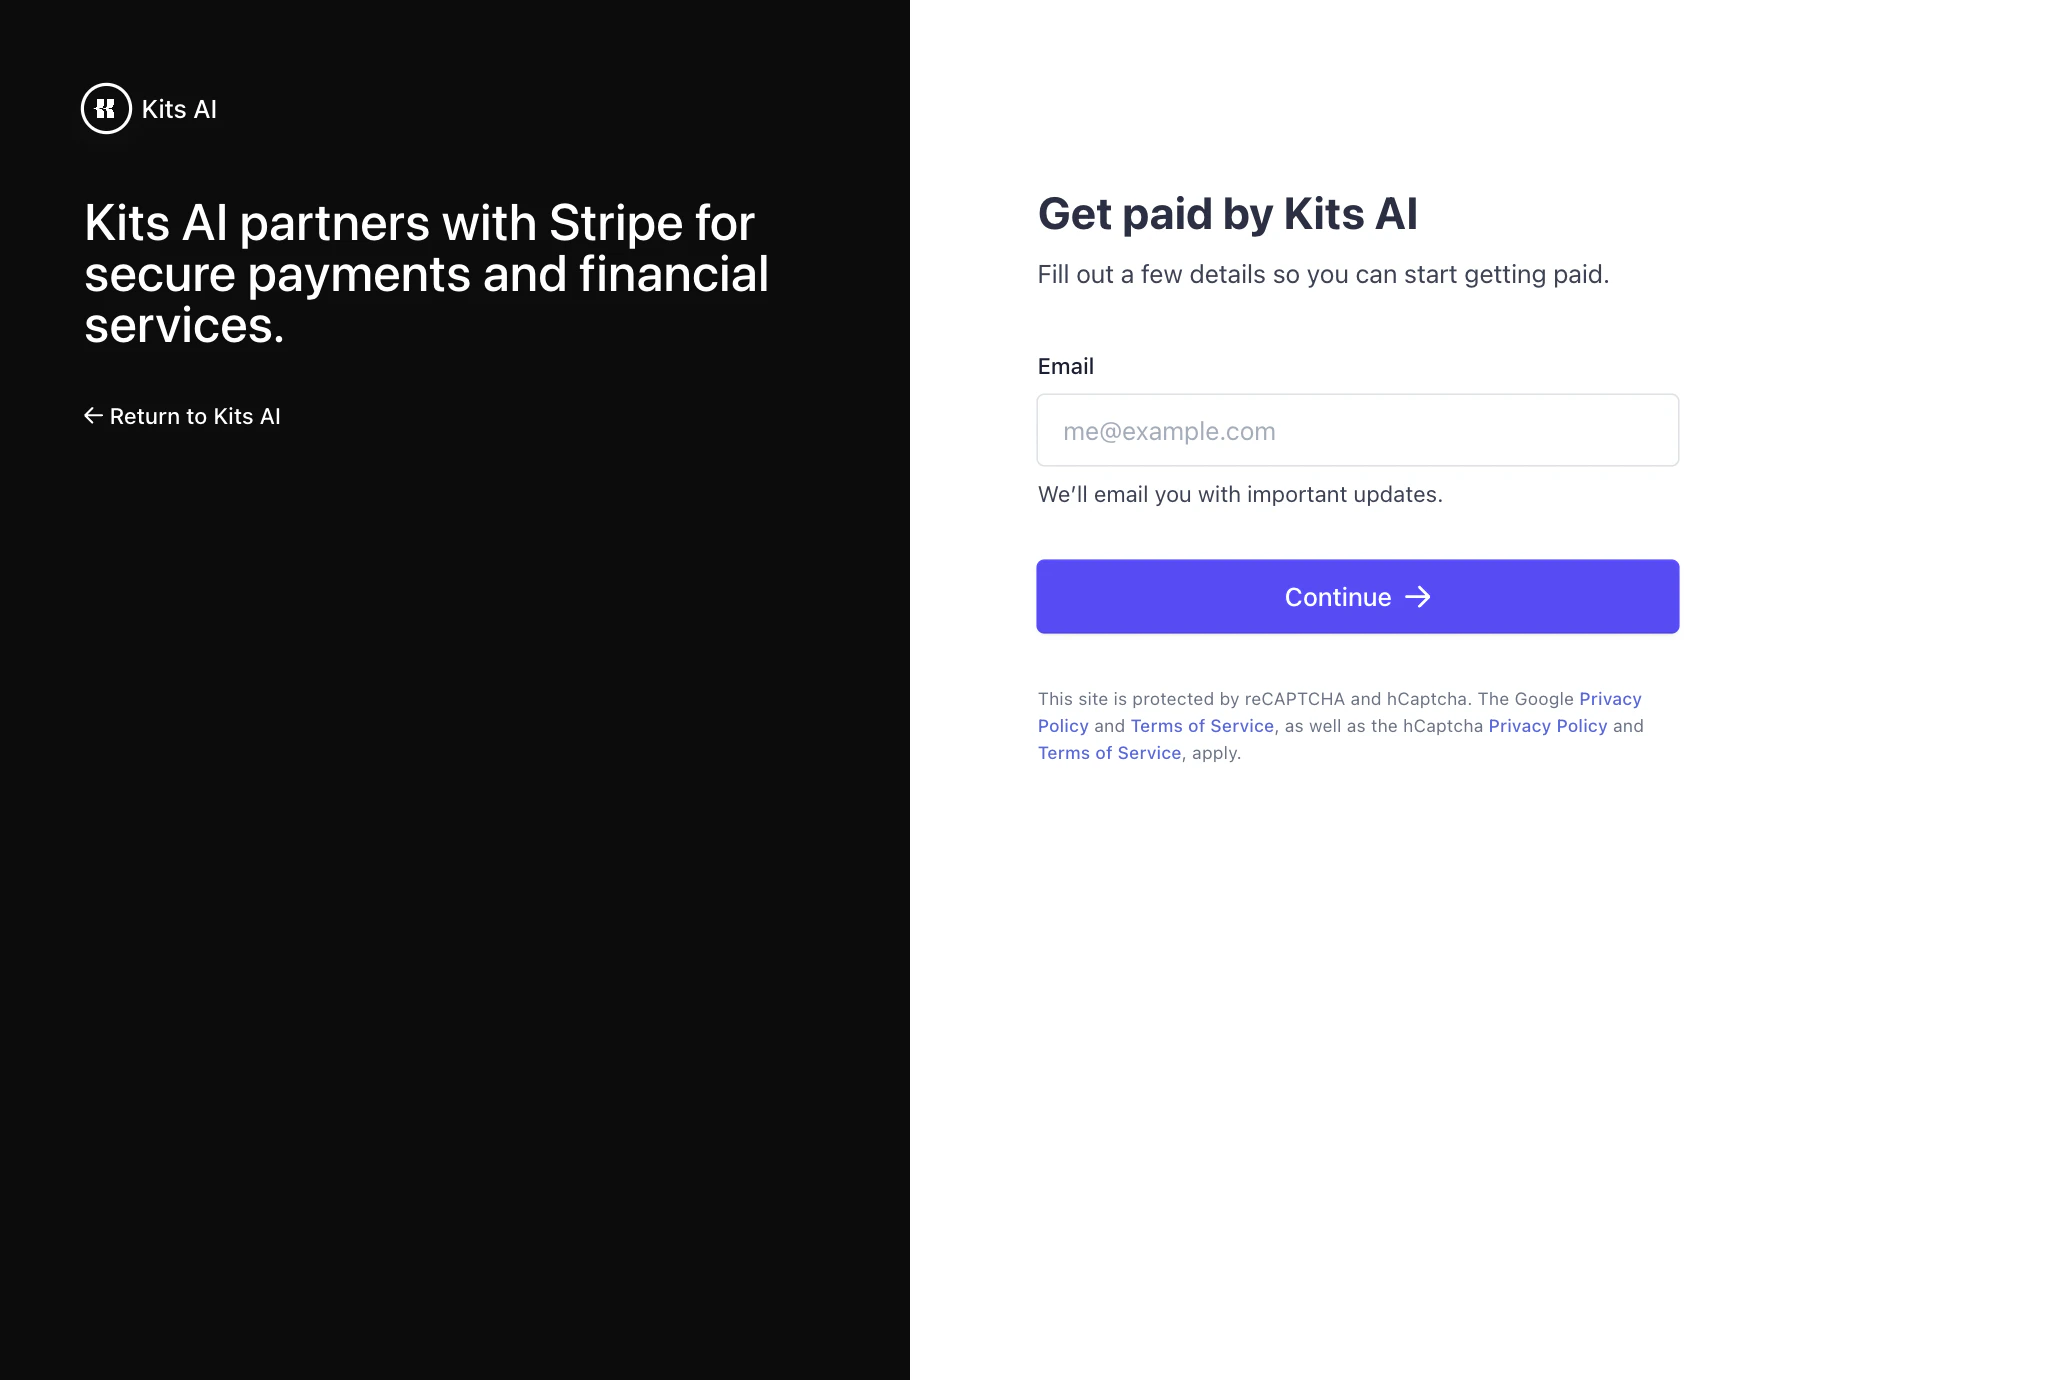
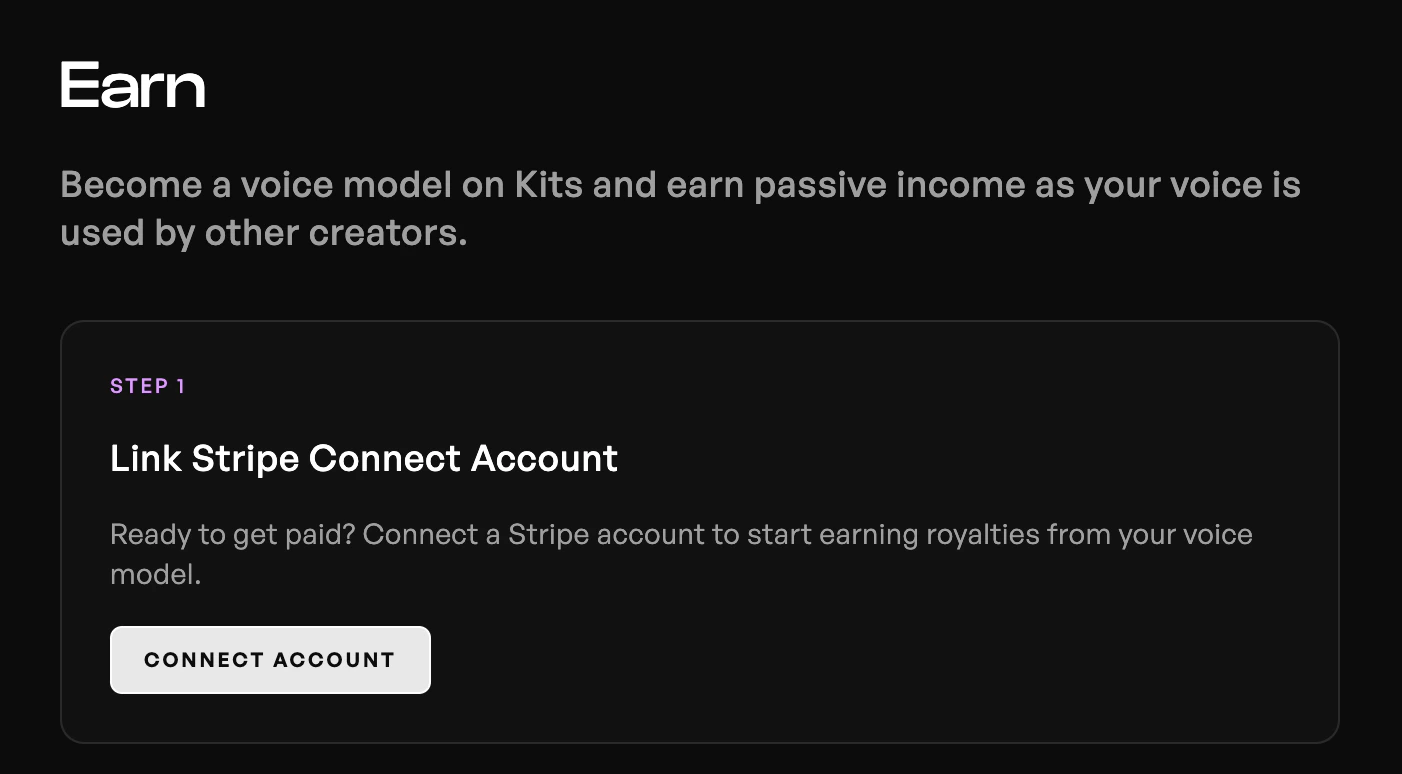 Follow the steps on screen to connect your Stripe to Kits.
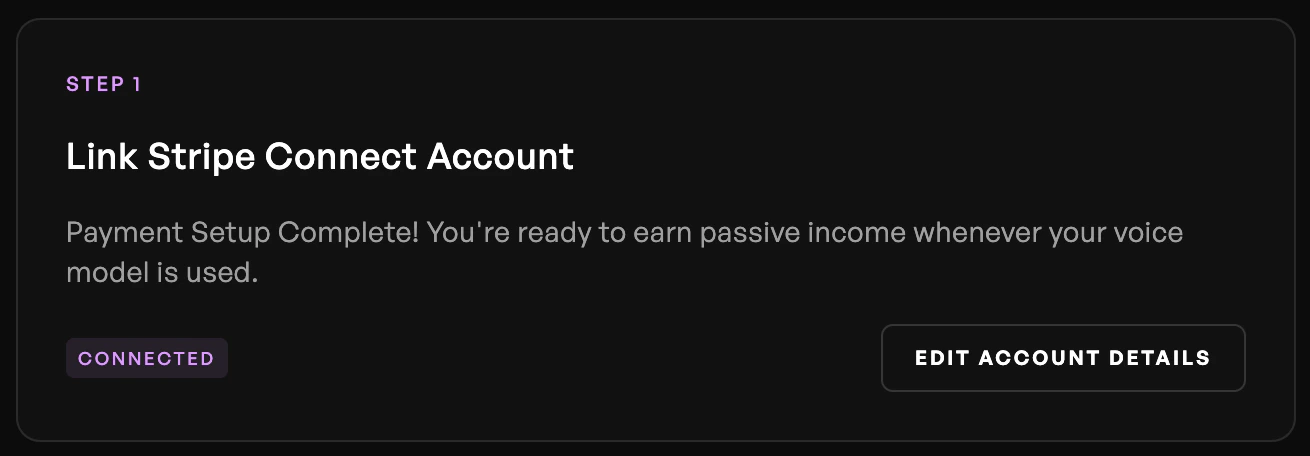
 Once connected successfully, the status on screen will change and you are ready to train / submit your voice!
 # Frequently Asked Questions
Source: https://docs.kits.ai/earn/frequently-asked-questions
FAQ for all things Kits Earn, from submission to payment.
## Frequently asked questions
You earn when users download outputs created using your voice model. Payments are processed on
the 1st and 15th of every month so long as your voice has accrued > \$10 in earnings. Full
details [can be found here](/earn/payments).
You may only submit 1 voice to Earn on Kits & that voice must belong to you.
Yes! You may submit your voice as yourself with your name, photo, and social links OR you may
submit your voice with anonymized branding. Either is allowed so long as the voice is yours and
we can verify that it is yours.
Yes! You may submit your voice for verification and then choose not to publish your voice
publicly. You will earn only when users you add via email use your voice. [Read more
here](/earn/publish-your-voice)
Yes, the voice must belong to you. The submission process includes a verification where we
compare your vocal audio to the audio that you train. If we doubt that the voice you submit
belongs to you, we will reject your submission.
The voice you submit must be trained using [Kits Voice
Cloning](https://app.kits.ai/voices/train). No merged or uploaded voices will be considered.
# Introduction
Source: https://docs.kits.ai/earn/getting-started
Introducing Kits Earn, a way for vocalists to earn passive income by creating a digital clone of their voice.
## What is Kits?
Kits is an AI voice platform used by 5,000,000+ artists, creators & producers worldwide to change the voice of their content. Imagine you’re a producer and you need a female vocalist for a harmony on your track. Instead of locating, hiring, and bringing that person to a recording studio, the producer can use an AI voice clone of a female voice, and create their female harmony right from the comfort of their home.
## What is Kits Earn?
Kits Earn is a way to bridge the gap the between vocalists and AI, providing passive income to vocalists who create, verify, and share digital clones of their voice for other users. With Kits Earn, when a producer downloads content created with your vocal model, you get paid.
## Why should I participate in Kits Earn?
Cloning your voice with Kits has already been used to streamline collaboration between artists and producers all over the world, enabling asynchronous recording sessions and collaborations that would otherwise be impossible. Kits Earn goes one step further, not only streamlining workflows and allowing for new opportunities, but enabling you to be compensated as it happens.
We believe that Kits Earn furthers our mission of using AI to support artists & creators, not replace them. Kits Earn puts the agency back into the hands of vocalists and producers alike, participating directly in ethically-sourced AI-generated voices while receiving passive income.
Read our step-by-step guide for submitting your voice for verification and start earning passive
income on Kits.
## What about privacy?
While some artists use Kits Earn to help promote their name and brand, we have also designed Kits Earn to support private use cases.
* Although releasing your voice to the Kits Verified Voice Library is the best way to get visibility, usage, and passive income, accepted voices are private by default and your voice does not need to be public if you do not want it to be.
* Your voice model must be of your voice, but it does not need to have your name or likeness attached
to it. Give your voice an anonymous name and image instead!
## How does Kits Earn work?
Kits creators can use [Kits voice training](https://app.kits.ai/voices) to train a custom AI
clone of their voice and then [submit their voice to the Kits team for
verfication](https://app.kits.ai/earn).
The Kits team reviews all voices submitted to validate that each voice belongs to the person who
submitted it and is of sufficient quality to be used by artists & producers.
Verified voice models begin earning passive income immediately from users who have access to the
model via email share. Verified voices are also eligible to join the Kits Verified Voice
Library, where they are accessible to 5,000,000+ Kits users.
## Frequently asked questions
You earn when users download outputs created using your voice model. Payments are processed on
the 1st and 15th of every month so long as your voice has accrued > \$10 in earnings. Full
details [can be found here](/earn/payments).
You may only submit 1 voice to the Verified Voice Library & that voice must belong to you.
Yes! You may submit your voice as yourself with your name, photo, and social links OR you may
submit your voice with anonymized branding. Either is allowed so long as the voice is yours and
we can verify that it is yours.
Yes! You may submit your voice for verification and then choose not to publish your voice
publicly. You will earn only when users you add via email use your voice. [Read more
here](/earn/publish-your-voice)
Yes, the voice must belong to you. The submission process includes a verification where we
compare your vocal audio to the audio that you train. If we doubt that the voice you submit
belongs to you, we will reject your submission.
The voice you submit must be trained using [Kits Voice
Cloning](https://app.kits.ai/voices/train). No merged or uploaded voices will be considered.
# Payments
Source: https://docs.kits.ai/earn/payments
Instructions for monitoring your earnings and understanding the payment process for your verified verified voice.
## Monitoring your earnings
Monitoring your earnings for your verified voice is extremely easy. Navigate back to the [Earn](https://app.kits.ai/earn) page and you will have a dashboard to track your voice's consumption and earnings. From this dashboard, you can see:
* Lifetime earnings
* Earnings in the current pay period
* Earnings and usage per day
## How payments work
* You accumulate passive income when users download audio that they created using your model. The rate at which you earn can be found in the table below.
* Models must accrue \$10 in earnings before being eligible for payment.
* Payments will be processed on the 1st and 15th of every month.
| Tier | \$ / download minute |
| ------------ | -------------------- |
| Starter | \$0.20 |
| Producer | \$0.20 |
| Professional | \$0.20 |
# Requirements
Source: https://docs.kits.ai/earn/requirements
Verification requirements for your voice on Kits
Before submitting your voice, you must first register with our payments processor, Stripe. Regualtions require us to collect taxpayer information from our users to ensure financial and legal compliance.
After you submit your voice, it undergoes a thorough review by the Kits team. We test each voice submission under two main criteria: quality and compliance. To ensure your voice passes our tests, please ensure that:
* The voice you submit is your own voice. We only accept voices submitted by the person who the voice belongs to.
* The voice you submit is of high quality. Please follow our guides [here](/earn/train-your-voice) for preparing high-quality datasets to train high-quality voices.
These checks are put in place to make sure that models featured in the Verified Voice Library are ethically sourced and retain the same high-quality standards as other AI models that we host.
# Step 5: Sharing your voice
Source: https://docs.kits.ai/earn/sharing-your-voice
Congratulations! Your submission is now a verified voice on Kits. Here is what happens next.
When your voice model is approved, you will receive an email from the team letting you know that your voice has become a verified voice on Kits! As soon as your voice is accepted:
* Your voice will get the gold badge and title of a verified voice.
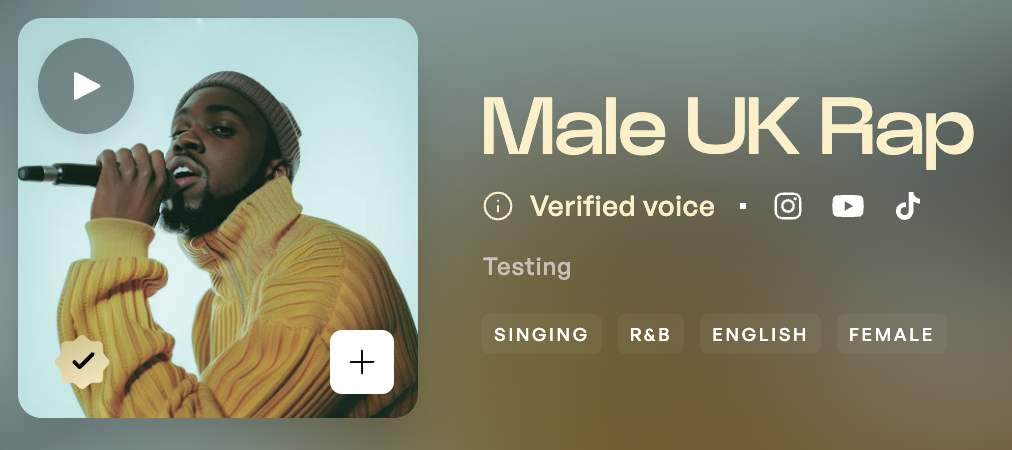 * You will immediately start earning from users who use your model from the email share feature.
{' '}
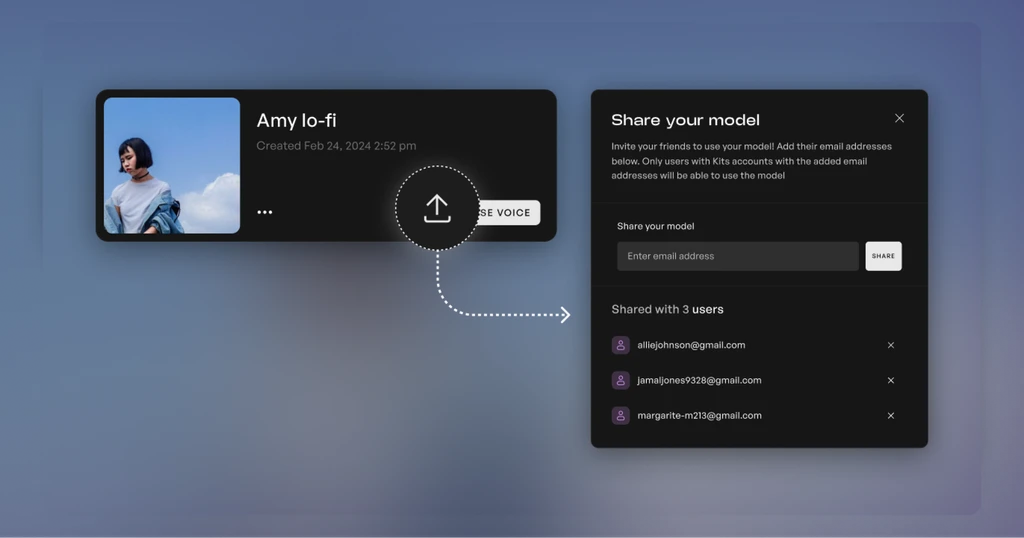 * If you selected that you'd like your voice to be published to the Verifed Voice library, your voice is in the final stages and will be published soon.
{' '}
# Step 3: Submit your voice
Source: https://docs.kits.ai/earn/submit-your-voice
Instructions for submitting your voice for verification.
{' '}
You are not required to submit a voice in your own likeness. So long as the voice is yours, you may
submit your voice anonymously.{' '}
## Submitting your voice
Now that you have connected your Stripe account and trained a voice, head back to the [Earn page](https://app.kits.ai/earn) and select **Submit Voice** to begin the submission process.
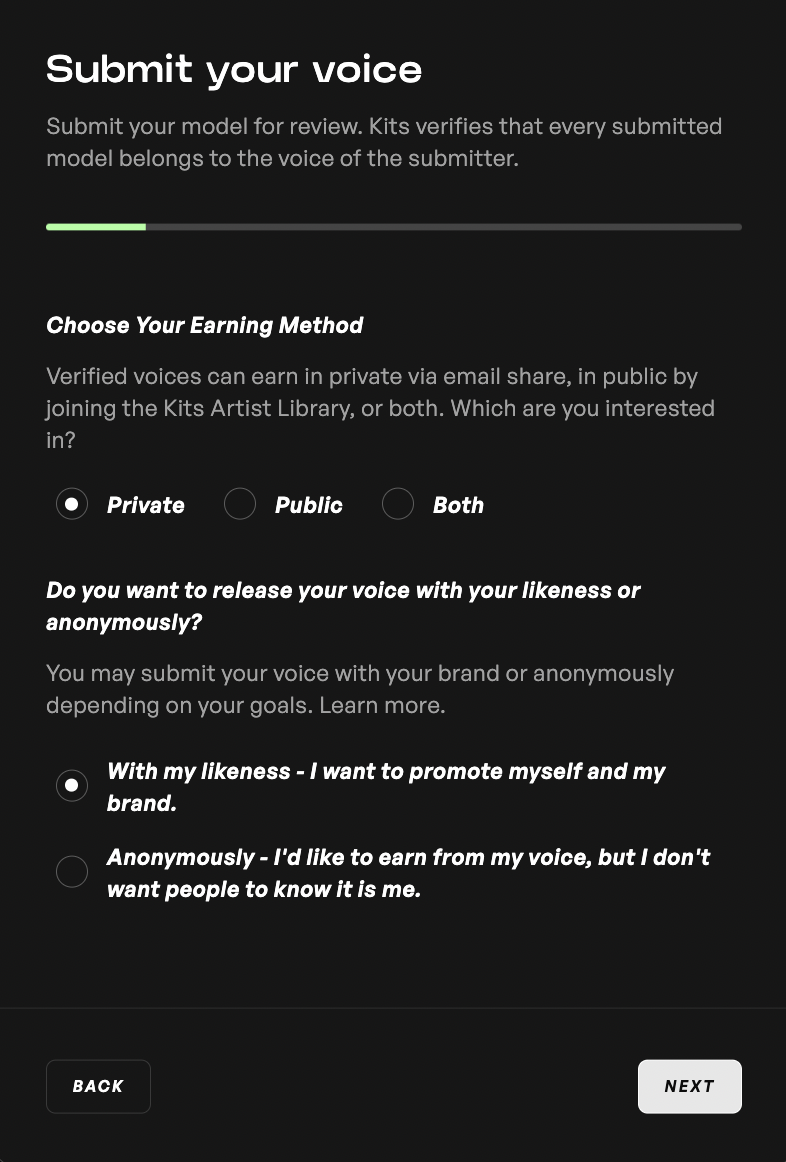
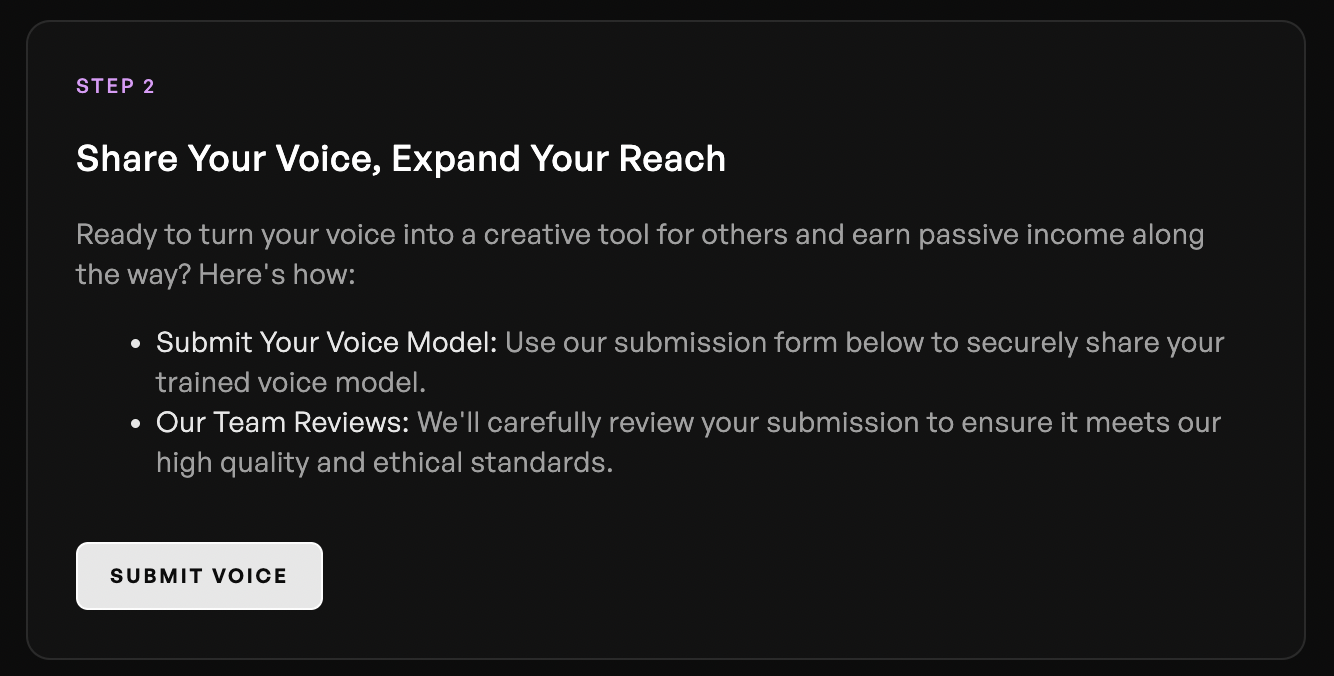 Start by selecting your earning method & your publishing type. This is your moment to decide if you want your voice to earn in public in the Verified Voices libary, in private via email share, or both. You may also select how your voice is packaged! It can use your likeness or be anonymous. Anonymous voice models are valuable for users who want to have the exposure of the Verified Voices library, but who want to remain anonymous. If you select anonymous, you don't have to worry about the packaging. So long as your voice model is high quality, we'll take care of branding & releasing it for you.
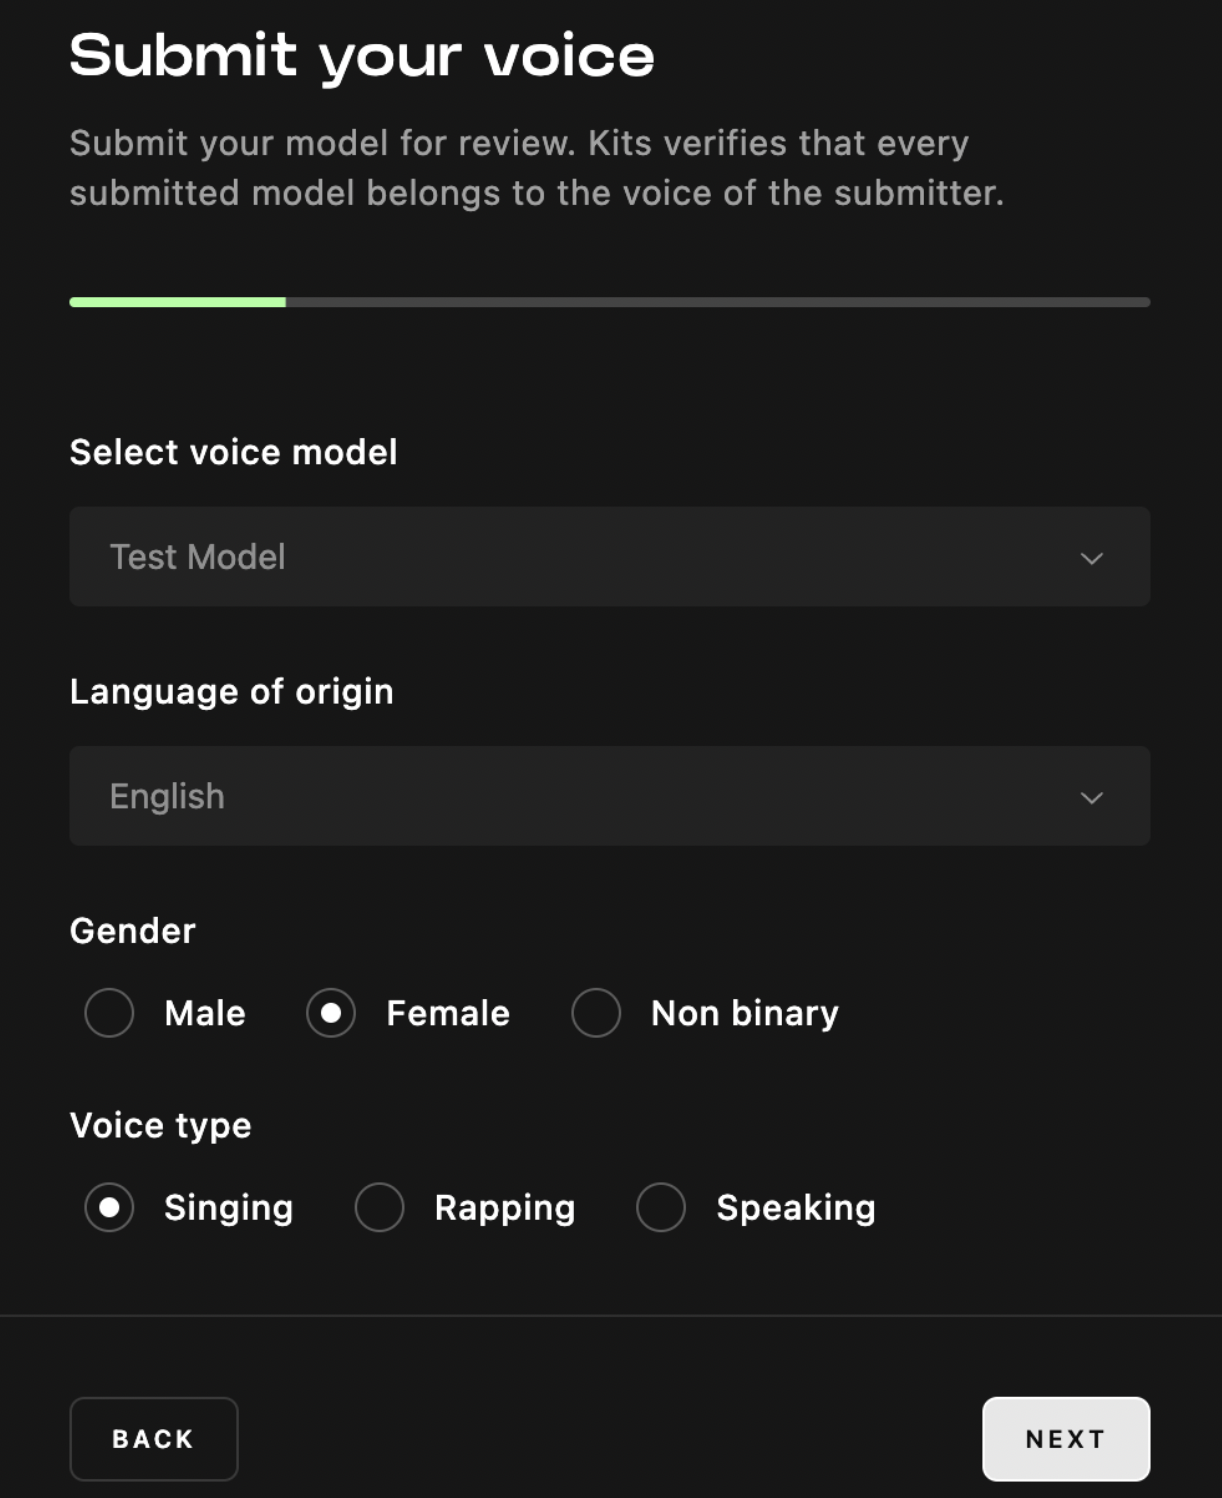
 Select the voice model that you’d like to submit for review and choose the relevant categories
for your voice.
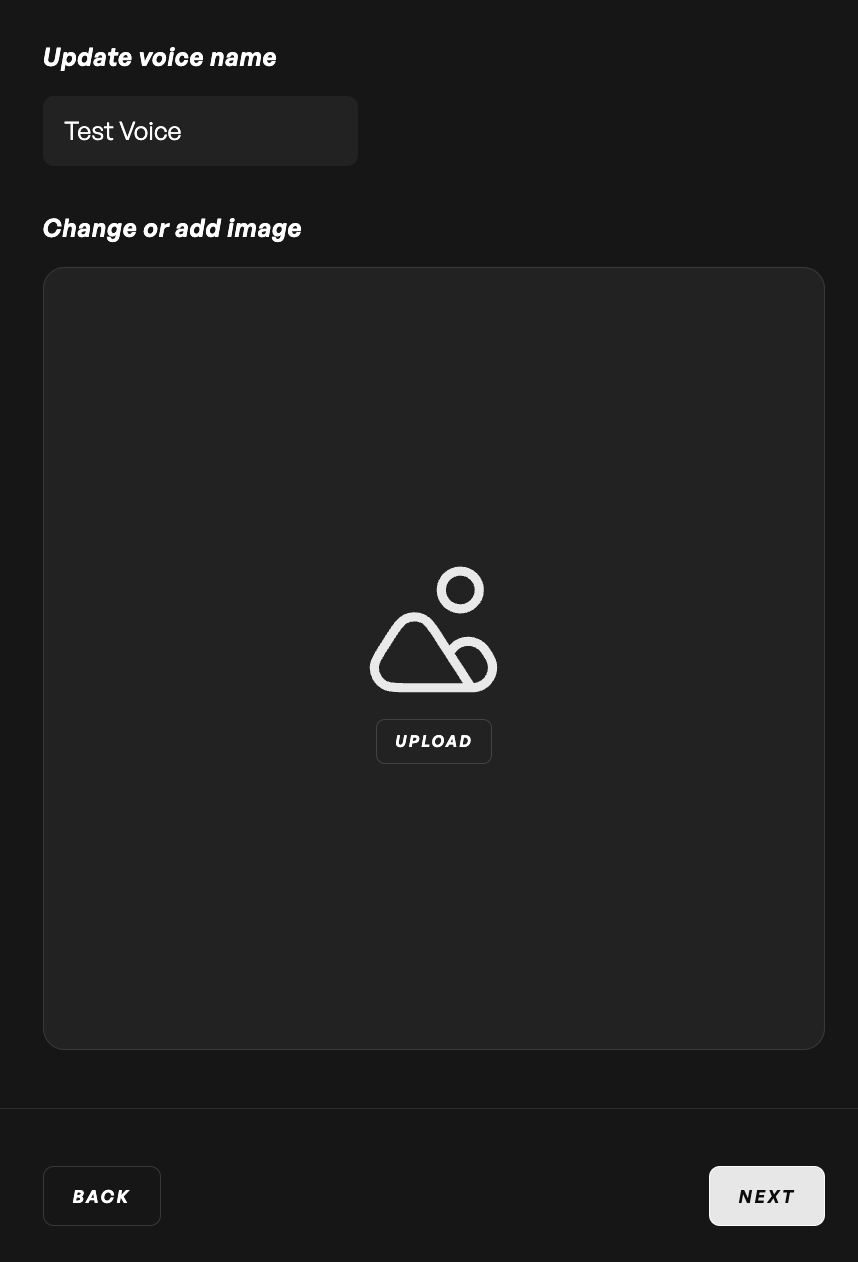
 Optionally update your voice's image and title. As a reminder, you are not required to submit a voice in your own likeness. So long as the voice is yours, you may
submit your voice anonymously.
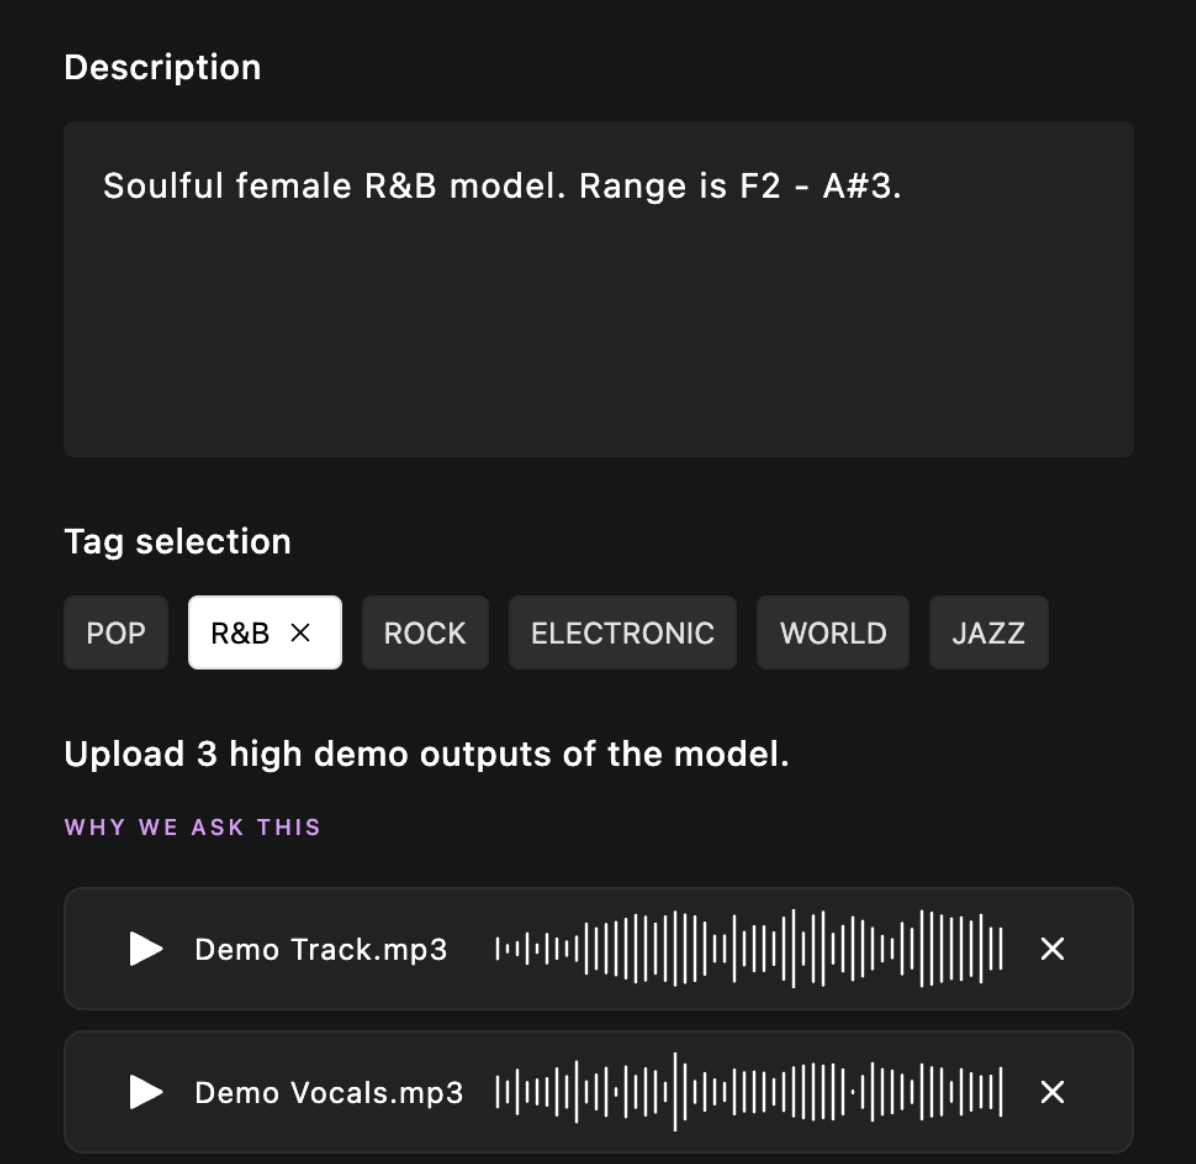
 Provide a description of your model, tags, and 3 high-quality outputs from your model. The tags
help us better understand your model and the audio outputs will be reviewed to ensure your
model’s quality.
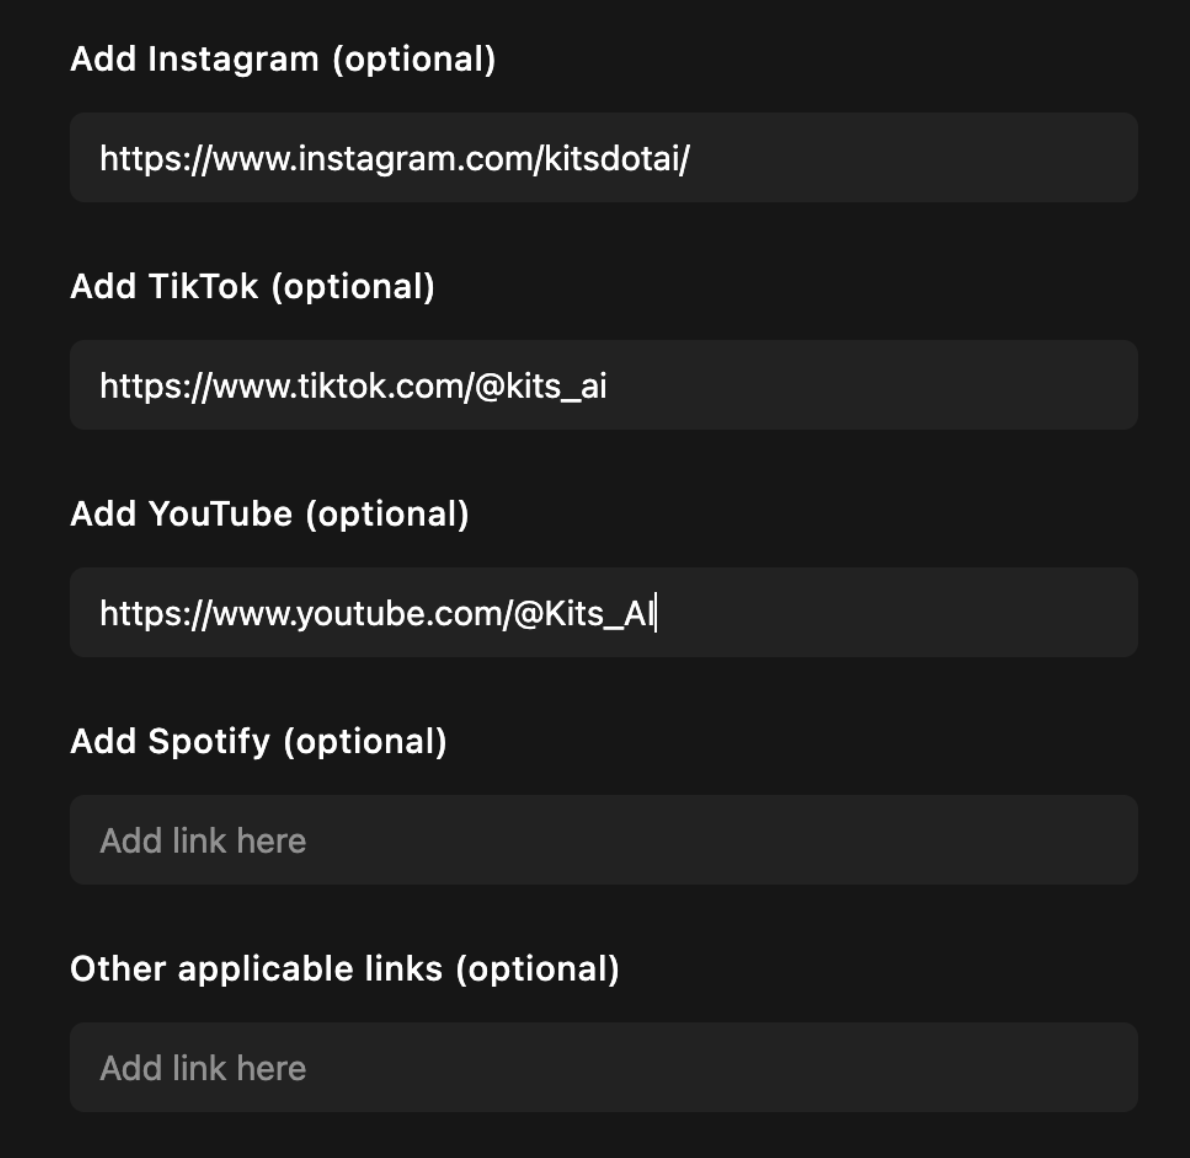
 Add any social media links or other links that you’d like to feature alongside your voice. This
step is optional if you'd like your voice to remain anonymous.
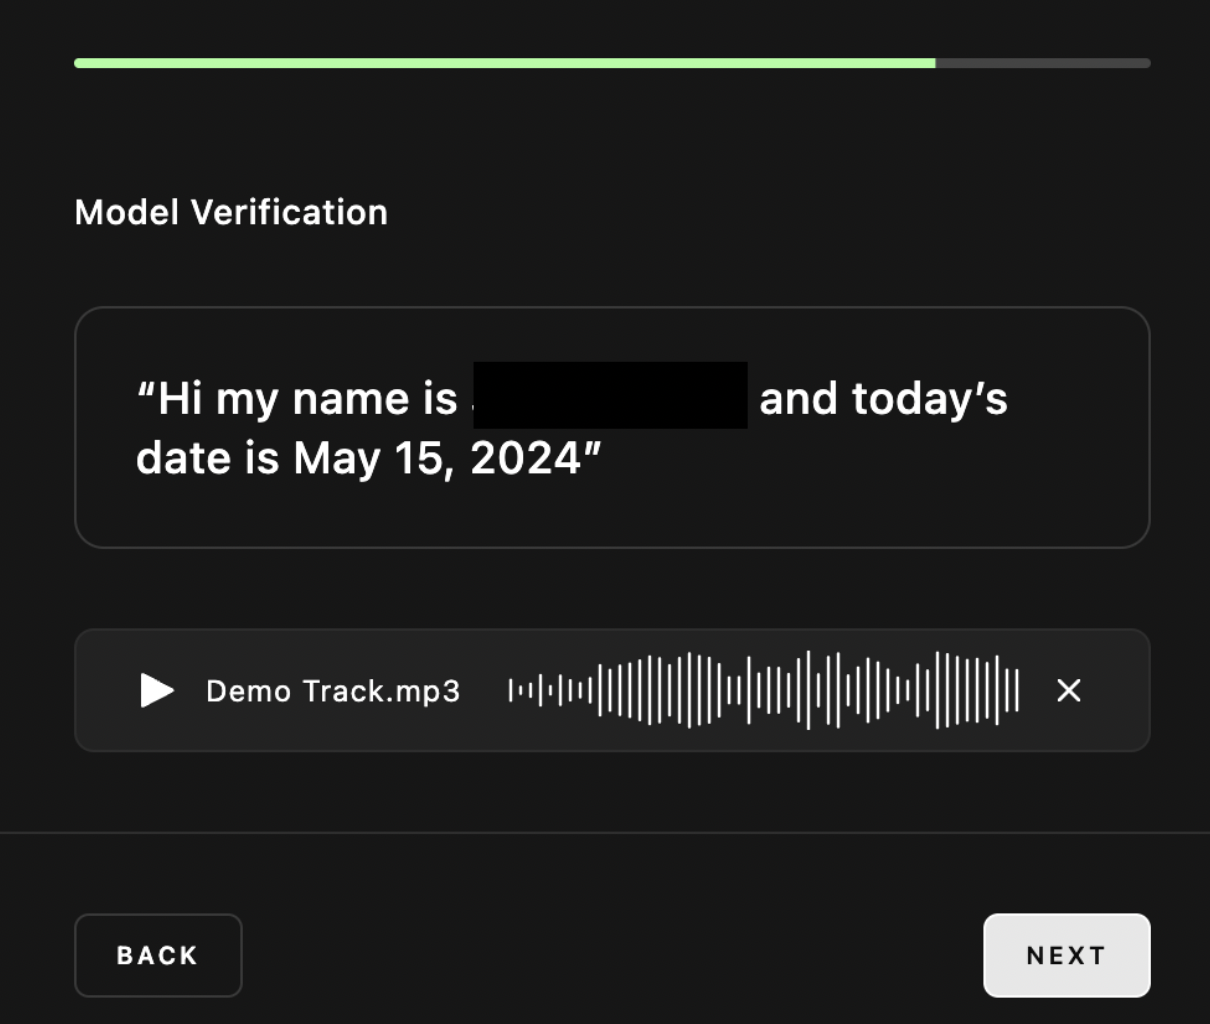
 To verify that your submitted voice belongs to you, provide a recorded response so we can
evaluate that the voice you are submitting is actually you.
 Lastly, agree to the Verified Voice Library terms, which are [outlined in full
here](https://www.kits.ai/verified-voice-model-marketplace-terms-of-service/).
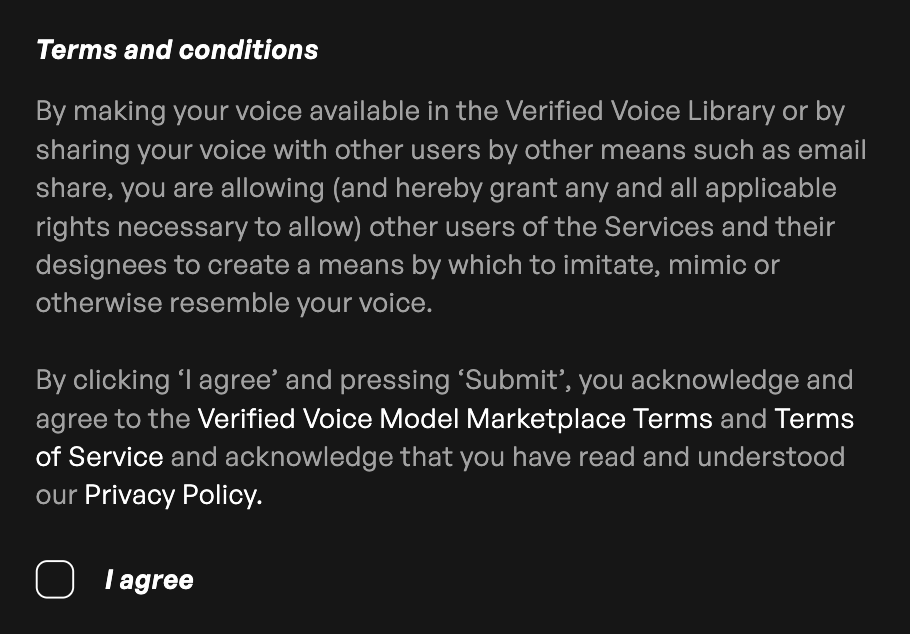 Once you have completed these steps, your voice model will be submitted for review.
# Step 2: Create your voice
Source: https://docs.kits.ai/earn/train-your-voice
Instructions for creating your voice model.
## If you already have a voice model trained...
You can [go to the next step!](/earn/submit-your-voice)
## If you have yet to create a voice...
Follow these instructions to train your first voice to be able to start earning passive income.
Only trained voices of your voice are eligible. Merged voices cannot be submitted for
verification.
Voice model creation is currently limited to our premium tier users.
To create a voice to submit, go to Kits AI’s [voice creation page](https://www.app.kits.ai/voices) and select **Clone a voice**.
 We have put together a number of guides to help you create the best model possible. You can:
* Follow the guide on screen (pictured below), and [at this link](https://www.app.kits.ai/voices/train)
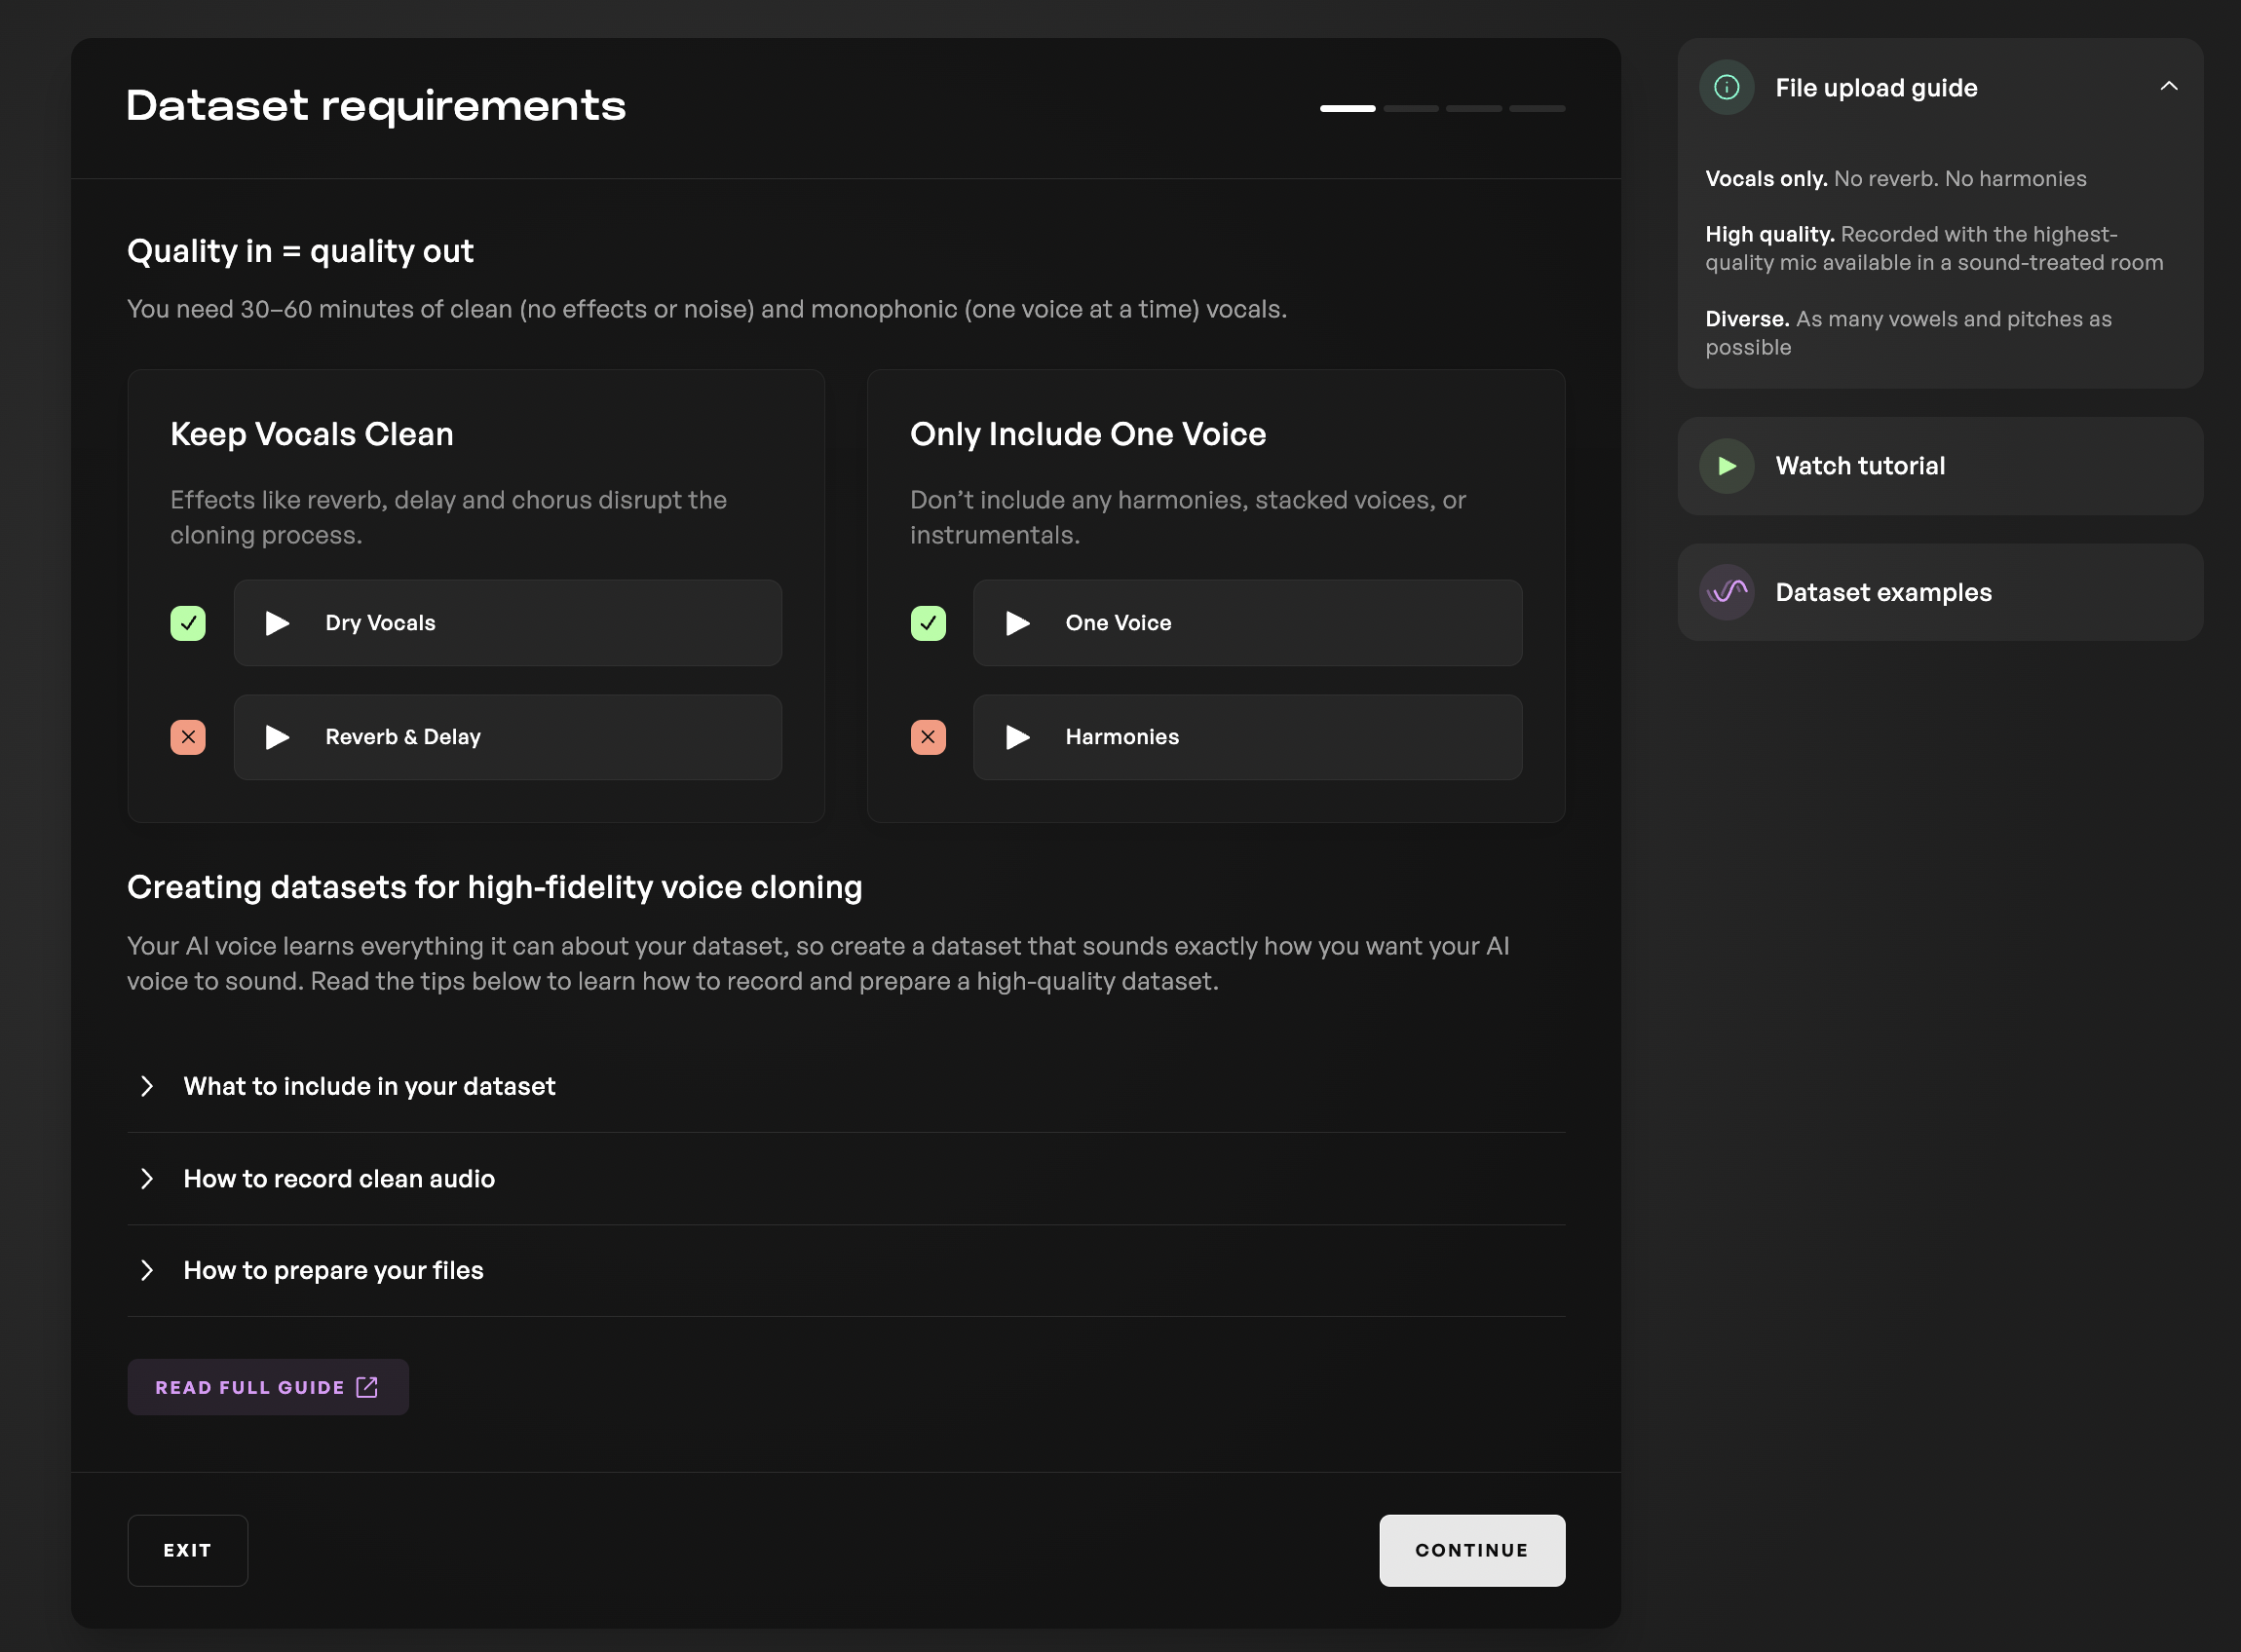 * Refer to our [written guide](https://www.kits.ai/blog/voice-model-creation-guide) for best practices; or
* Check out our [full documentation](https://docs.kits.ai/train/high-quality-datasets) for creating the best datasets possible.
After completing the training steps and pressing Train, your model will begin training and complete in accordance with time estimate on your progress bar.
{' '}
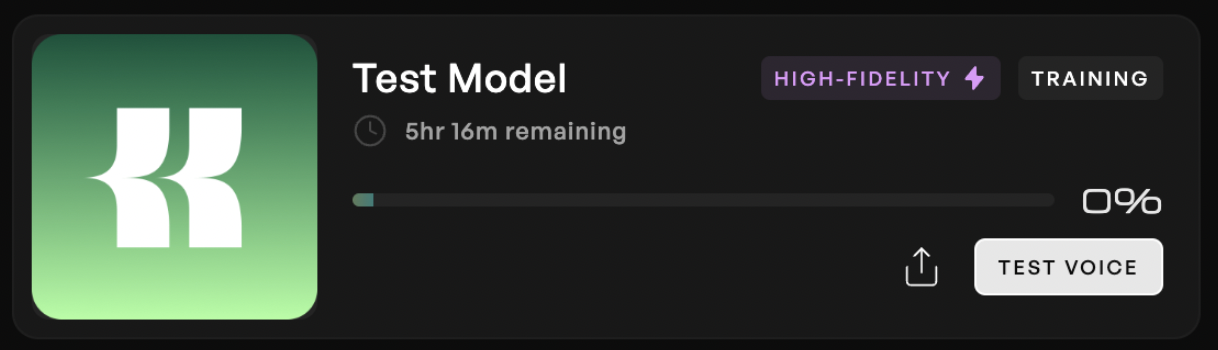 When finished, test your model out by pressing "Use Voice" and evaluate the model quality. If you are pleased, proceed to the [next step.](/earn/submit-your-voice)
# Step 4. Voice review
Source: https://docs.kits.ai/earn/voice-review
The Kits team now reviews your voice and gets back to you with an outcome.
## How we evaluate voices
The Kits team thoroughly reviews and tests each voice submission under two main criteria: quality and compliance. To ensure your voice passes our tests, please ensure that:
* The voice you submit is your own voice. We only accept voices submitted by the person who the voice belongs to.
* The voice you submit is of high quality. Please follow our guides [here](https://docs.kits.ai/train/high-quality-datasets) for preparing high-quality datasets to train high-quality voices.
These checks are put in place to make sure that models featured in our library are ethically sourced and retain the same high-quality standards as other AI models that we host.
## Submission status
After you submit your voice, it will be marked as pending. The Kits team will conduct a thorough review of your submission and either mark it as **Rejected** or as **Approved**. You will receive an email communication with your outcome.
* If your voice is rejected, you are welcome to resubmit another attempt. Your rejection email will contain feedback specific to your submission that you'll need to address to create a better model.
* If your voice is approved - congratulations! Your voice is now eligible for monetization on the Kits platform.
# Getting Started
Source: https://docs.kits.ai/home
Explore all that Kits AI has to offer with our API documentation and guides.
Build applications with the Kits AI API
Top tips on creating high-quality voices
Our payout program for artists and vocalists
# Audio Post-Processing
Source: https://docs.kits.ai/train/audio-post-processing
Enhance audio quality with Kits' post-processing training.
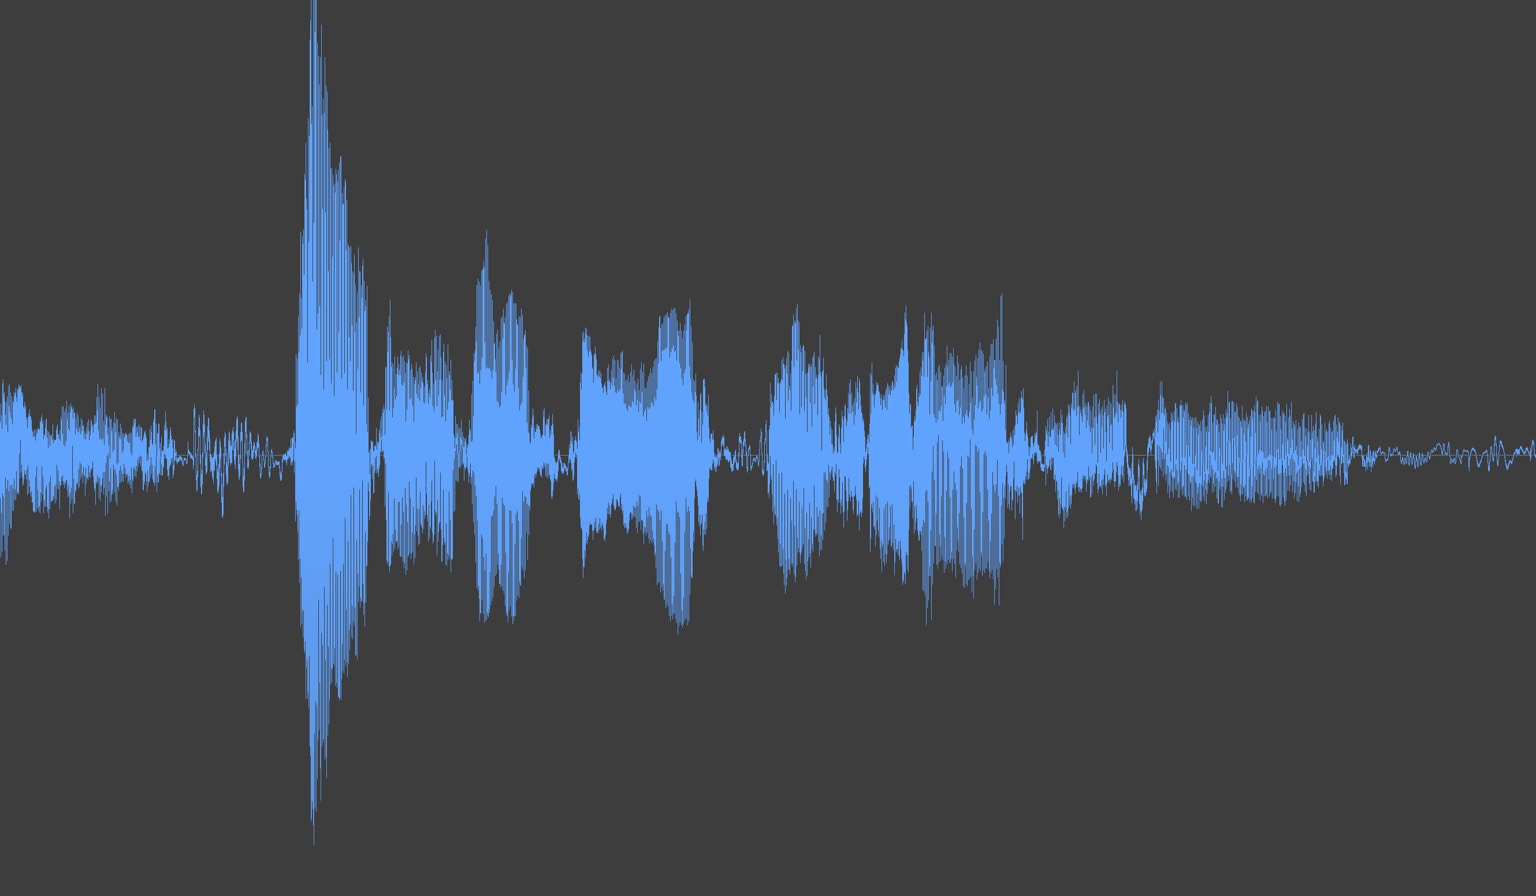
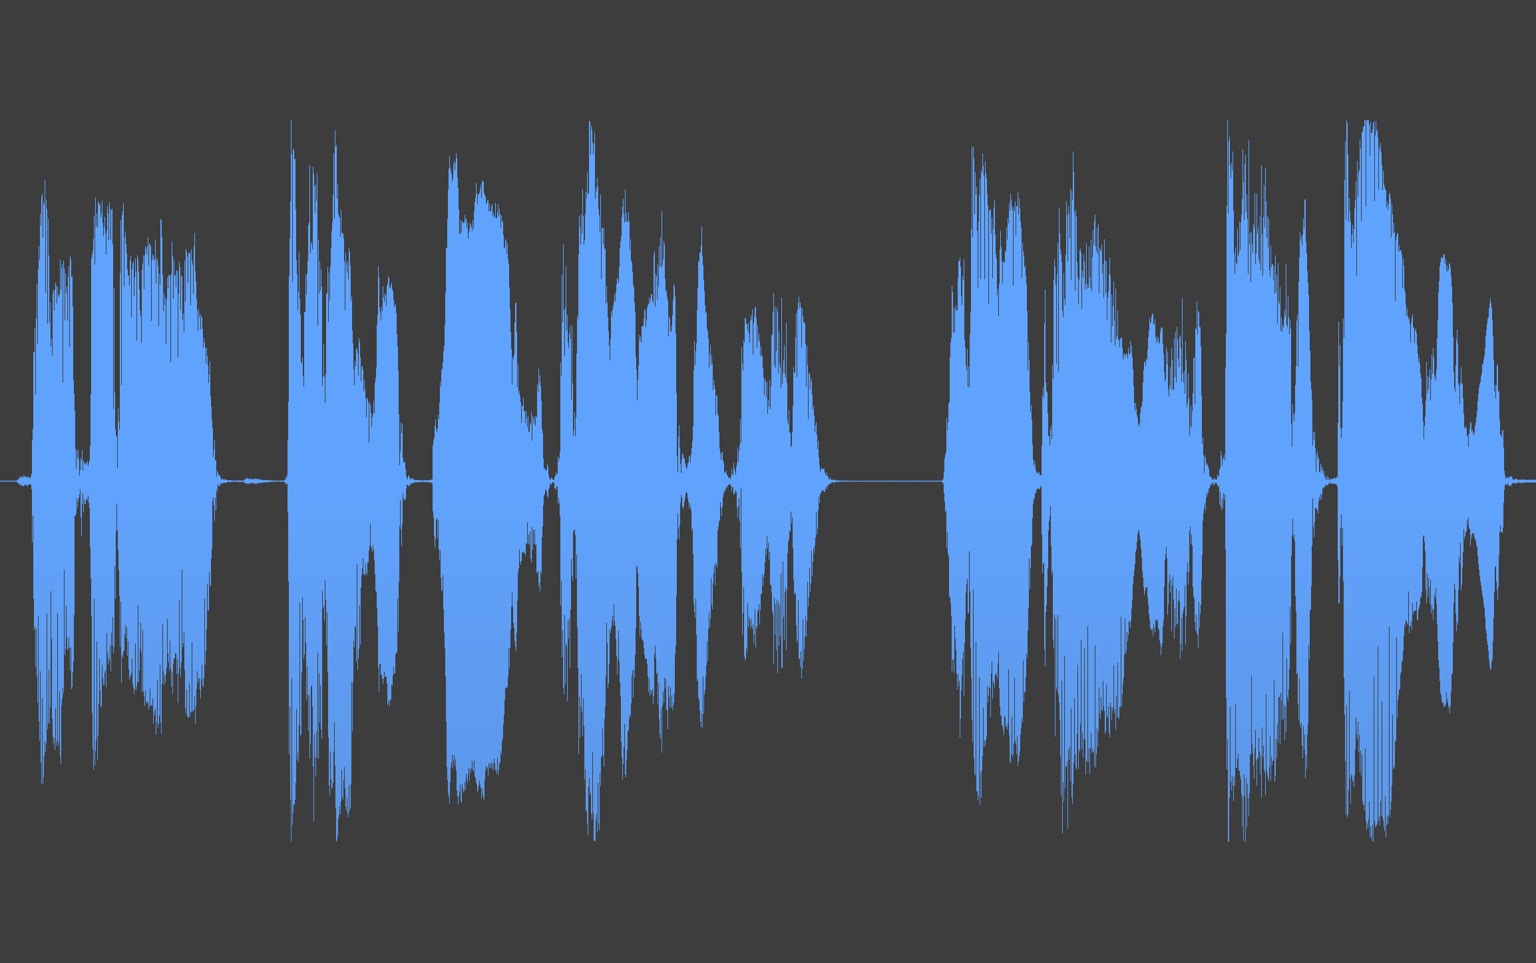
When preparing audio for AI voice cloning data or inference, the goal is to maintain the natural character and clarity of the target voice while ensuring consistency and cleanliness in the audio. Here’s a guide to subtle yet effective post-processing:
1. **Achieve consistent volume:** Use a volume rider or automation to make sure volume levels are consistent across your entire dataset. The aim is to create a consistent volume level across the recording while keeping the dynamics within sections.
2. **Smooth out peaks:** Use a transparent compressor or limiter with a fast attack to smooth out the peaks within sections. Try to limit dynamic range to around 5db.
3. **Phase balance your audio:** Using a tool like Izotope RX, you can phase balance your audio to maximize headroom before normalization.
4. **Normalize to -3db:** After smoothing out peaks and phase balancing, normalize your dataset to -3db.
5. **EQ for Cleanliness:** EQ primarily to remove unwanted frequencies. Cut out low-end rumble, mid-range muddiness, or high-end hiss to prevent your model from learning those unwanted qualities. Be cautious not to overdo it; subtle cuts are often enough.
6. **EQ to Match Vocal Style:** If needed, make EQ adjustments to enhance the vocal character. Add a slight boost for 'air' in the high frequencies for clarity or a small boost in the lower frequencies for 'weight.' Remember, the goal is to retain the vocal's natural tone, not to alter it significantly.
7. **Prevent Clipping:** Ensure the vocal track does not clip at any point. Clipping introduces digital distortion. Keep an eye on the meters to ensure levels stay below 0 dB.
8. **No Time-Based Effects:** Refrain from adding reverb, delay, or other time-based effects. These effects can obscure the clarity of the vocals and confuse the AI model's pitch detection.
9. **Avoid Hard Cuts:** When editing, avoid hard cuts that can create abrupt starts or ends. Such cuts can introduce clicks or pops. Use smooth fades at the beginning and end of the vocal track for a more natural transition.
10. **Don't Layer Vocals:** Multi-layered vocals can complicate the AI’s analysis. Stick to a single vocal track to ensure the AI can accurately process and learn from the recording.
11. **No Copying and Pasting Sections:** Avoid duplicating or artificially extending sections of the vocal track. The AI model benefits from the natural variation and imperfections of a continuous, unaltered performance.
 # Content Guidelines
Source: https://docs.kits.ai/train/content-guidelines
For a high quality voice clone, compile 30 to 45 total minutes of vocals recorded in a single session.
## What to include in your dataset
Collect about 20 minutes of confident singing examples in the style you want to clone. Then include an additional 10 minutes including examples of low notes, high notes, isolated phonemes, and sibilant sounds to make sure you’ve covered every possible sound. You should have 30+ minutes of content.
Your AI voice can only accurately reproduce what it hears in your dataset, so **include as many words and pitches as possible**. And whether it’s audio glitches or singing mistakes, **don’t include anything you wouldn’t want your AI voice to learn**.
* Voice cloning requires monophonic input, so do not include any vocal stacks or harmonies.
* Record your dataset in a single session so your AI voice can capture the exact frequency response of the target voice. Combining different recordings can reduce the accuracy of the cloning process.
* Decide what vocal quality you would like to clone. For example, if you want your AI voice to have a gritty character when singing high notes, don’t include falsetto vocals in the same pitch range as gritty vocals.
### Optional lyrics to make sure your dataset is complete
The following lyrics contain every phoneme in American english. You can use these lyrics with a variety of articulations and melodies for a quality dataset.
*In the land where dreams gleam the serene breeze weaves melodies that seize hearts and minds.*
*The bright light ignites the night, as whispers rise and dive, alive with a tapestry of timeless rhymes.*
*Through the wilderness, I navigate, zealous through determination my voice resonates and wraps with grace and might.*
*A symphony of vowels and consonants unite, captivating as the journey unfolds, granting us insight.*
*From the valleys to the peaks, a kaleidoscope of sounds cascades and seeks to reach infinite heights.*
*Let us harmonize, mesmerize, and improvise, with linguistic hues that ignite our spirits' flights.*
#### Additional Lines
The following lines are great for making sure your dataset includes essential sibilant sounds and rare phonemes.
*Chefs toss fresh fish with thick salt, chop hot peppers, and pack them swiftly into shiny dishes.*
*The quick brown fox jumps over the lazy dog while vexing my soul with five dozen liquor jugs.*
*Manny's mini van makes many Monday morning trips.*
*Paul packs purple peppers by the peck.*
*Vivian finds valuable fossils for fun.*
*Theo thought thirty-three thieves threw through.*
*Tod takes time to tackle tough tasks.*
*Nina's new neighbor needs nice notes.*
*Sally sells seashells by the seashore.*
*Larry likes learning languages late at night.*
*You yield yellow yarn yearly.*
*Shea shares shiny shoes on Saturday.*
*Kara's cat keeps catching kites.*
*The singing king brings ringing.*
*He highlights high, heavy hurdles happily.*
# File Quality Settings
Source: https://docs.kits.ai/train/file-quality-settings
Set up your project to capture high-quality audio for your voice model.
The audio quality of your training data directly impacts the quality of your model. To make sure your conversions have a wide frequency range and realistic dynamics, set your project settings before you record your audio.
## Recommended Settings
At least 16-bit
44.1khz or 48khz
Lossless (.wav or .aiff)
## How to change file settings in your DAW
#### 1. Ableton Live
* **Change Bit Depth:** `Preferences` > `Record` > `Bit Depth`.
* **Change File Type:** `Preferences` > `Record` > `File Type`.
* **Change Sample Rate:** `Preferences` > `Audio` > `In/Out Sample Rate`.
#### 2. Logic Pro X
* **Change Bit Depth:** `Preferences` > `Audio` > `General` > `Recording` > `Audio Bit Depth`.
* **Change File Type:** (Logic Pro records in .aiff by default). For other options, when bouncing a project, choose `File` > `Bounce` > `Project or Section`, then select file type under `Destination`.
* **Change Sample Rate:** `File` > `Project Settings` > `Audio`, then adjust `Sample Rate`.
#### 3. FL Studio
* **Change Bit Depth:** `Options` > `Project General Settings` > `Timebase (PPQ)` (indirectly affects bit depth in project).
* **Change File Type:** (FL Studio records in .wav by default). For other options, when exporting, `File` > `Export` and choose the desired format.
* **Change Sample Rate:** `Options` > `Audio Settings` > `Sample Rate`.
#### 4. Pro Tools
* **Change Bit Depth:** When creating a new session, choose `File` > `New Session`, then select `Bit Depth`. To change in existing session, `Setup` > `Session` > `Bit Depth`.
* **Change File Type:** `Setup` > `Preferences` > `Processing` tab, and under `Audio File Format`, choose the desired format for new recordings.
* **Change Sample Rate:** When creating a new session, choose `File` > `New Session`, then select `Sample Rate`. To change in existing session, `Setup` > `Session` > `Sample Rate`.
#### 5. Cubase
* **Change Bit Depth:** `Project` > `Project Setup`, then adjust `Record Format`.
* **Change File Type:** `Project` > `Project Setup`, then adjust `Record File Format`.
* **Change Sample Rate:** `Project` > `Project Setup`, then adjust `Sample Rate`.
#### 6. Reaper
* **Change Bit Depth:** `File` > `Project Settings` > `Media` tab, then set `Format for new audio recordings`.
* **Change File Type:** `File` > `Project Settings` > `Media` tab, then select `Format for new audio recordings`.
* **Change Sample Rate:** `File` > `Project Settings`, then adjust `Project Sample Rate`.
## Latency Issues
In computer based audio systems a certain amount of latency, known as audio buffering, is necessary to ensure that playback, recording and processing results in an error-free audio stream. However, if the buffer size is set too low, then crackles, static noise, pops or dropouts may occur.
# Recording High-Quality Datasets
Source: https://docs.kits.ai/train/high-quality-datasets
30-60 minutes of clean and varied audio will result in the highest-quality voice models.
## Clean audio
The highest-quality voice models are recorded:
* with a [quality microphone](/train/microphones-audio) into an [audio interface](/train/microphones-audio)
* in a [noise-free setting with limited room reverberations](/train/recording-environment)
* with [correct and consistent mic placement](/train/microphone-placement)
* with [volume peaks between -9db and -3db](/train/volume-level)
And [processed](/train/audio-post-processing):
* with consistent dynamics across the whole dataset
* with light EQ to remove any muddiness, hiss, etc.
* with compression/limiting to smooth out peaks
* with no reverb, delay, or doubling
# Microphone Placement
Source: https://docs.kits.ai/train/microphone-placement
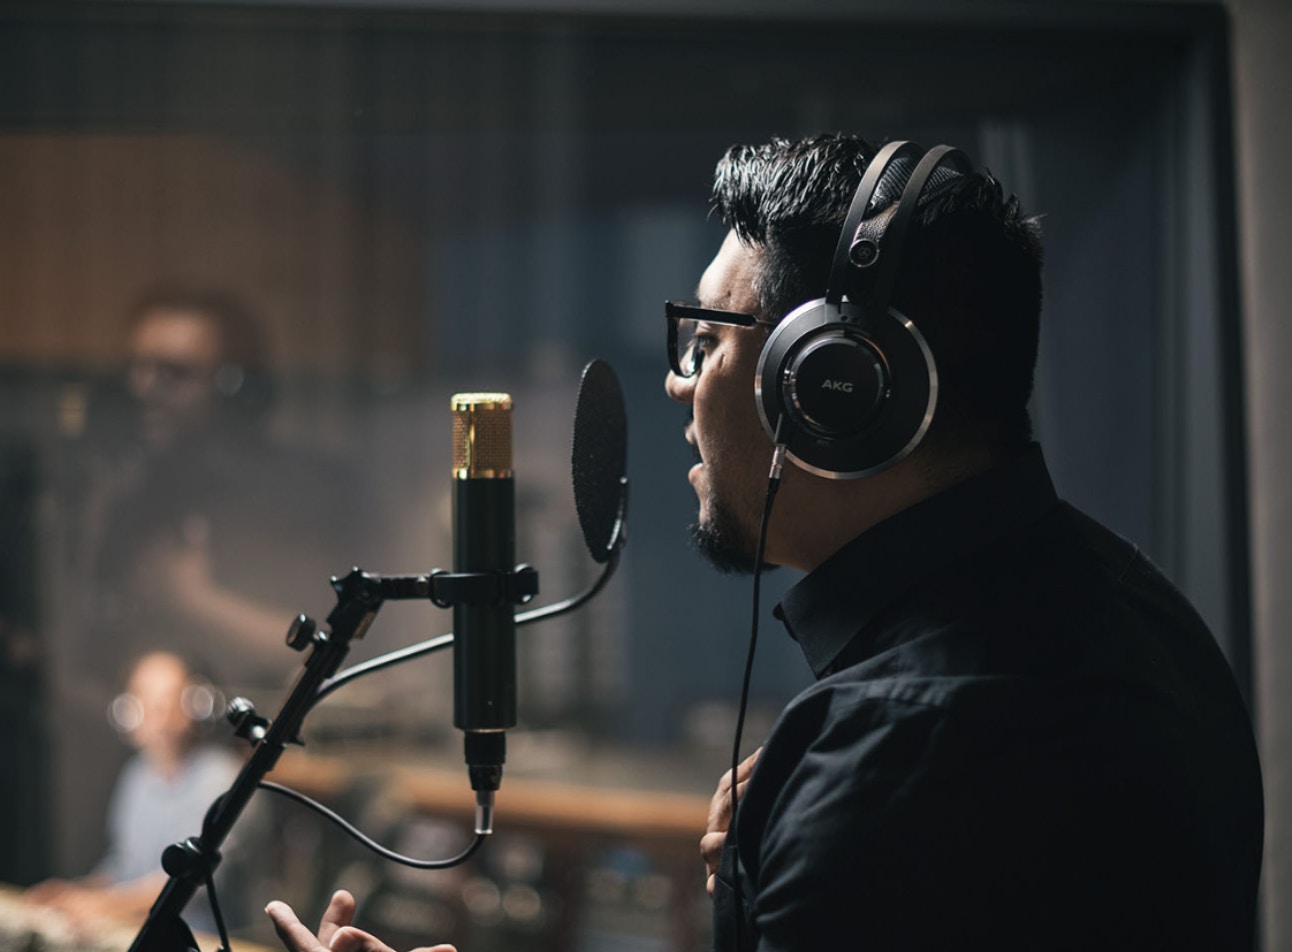
You should be about 2 inches from the microphone for your regular volume and 4-6 inches for louder phrases/belting. Always be closer than 12 inches from your microphone.
 ### Pro Mic Technique
* Avoid moving the microphone during phrases. Set your distance, then maintain it.
* Sing straight into the microphone’s capsule. Don’t be angled.
* Don’t cover the microphone with your hand.
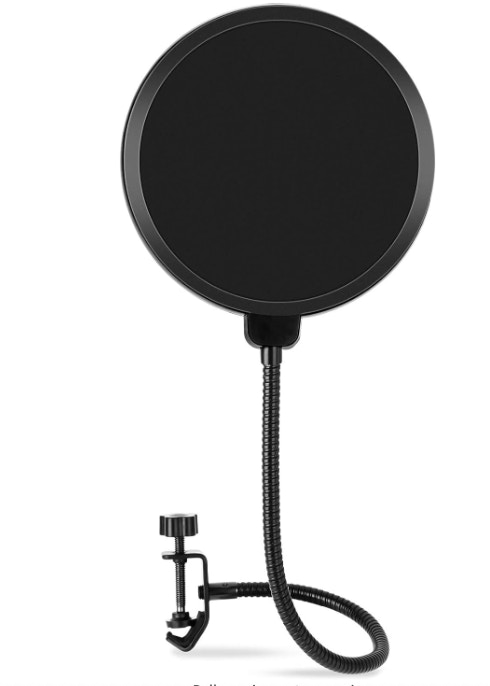
* Place a pop filter 1 inch from the mic to limit plosives
 * Don't use an "eyeball" to avoid excessive isolation and overloaded mic capsules.
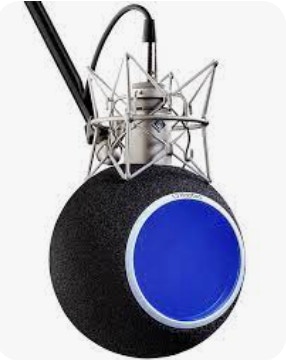 Don’t enclose your mic with a Kaotica Eyeball or similar.
# Microphones & Audio Interfaces
Source: https://docs.kits.ai/train/microphones-audio
With just a few essential pieces of equipment, you can achieve professional-quality recordings. Here's what you need for a minimalist yet effective vocal recording setup:
## **1. Quality Microphone**
**Condenser microphones**
Considered the industry standard for their volume sensitivity and wide frequency response, large-diaphragm condenser microphones are the upgrade pick for recording vocals. These mics can capture all the nuance of the voice, but if you're working in a noisier environment or on a tighter budget, a dynamic microphone can also do a great job.
**Dynamic microphones**
Dynamic microphones are versatile, durable, reliable, and relatively inexpensive. They are better at handling high sound levels and are less sensitive to ambient noise than condenser mics. This makes them a common choice for live music settings.
**Mics to avoid**
When recording for a voice model, avoid microphones that are intended for purposes other than singing.
* Laptop or phone mics
* Lapel mics
* Karaoke Mics
* Headset mics
* USB or 1/8" input mics (these *can* be high quality, but most are intended for communication and not studio-quality recording)
## 2. Audio Interface
This is the bridge between your microphone and your computer. A good audio interface converts the analog signal from your microphone into a digital format for recording and playback. Look for an interface with high-quality preamps and at least one microphone input (XLR input). USB interfaces are popular for their ease of use and compatibility with most computers.
## 3. Recording Software
You'll need some type of Digital Audio Workstation (DAW) software to record, edit, and mix your vocals. There are many options available, ranging from free to professional-grade.
#### Free DAWs
1. **Audacity:** A completely free, open-source DAW that's great for beginners. While it lacks some advanced features, it's perfect for simple recording and editing.
2. **Cakewalk by BandLab:** A fully-featured DAW that's available for free. It offers a range of professional tools suitable for most recording needs.
#### Budget-Friendly DAWs
1. **Reaper:** Known for its affordability and flexibility. It's not free, but its pricing is much lower than many professional DAWs, and it offers a wide range of features.
2. **FL Studio Fruity Edition:** A more affordable version of FL Studio, offering essential tools for music production, minus some advanced recording and editing features.
#### Mid-Range DAWs
1. **Ableton Live Intro:** A more accessible version of Ableton Live, offering many of the key features of the full version but with some limitations in track count and other areas.
2. **Logic Pro X:** Exclusive to macOS, Logic Pro X is a favorite among home studio enthusiasts and professionals alike, offering a vast range of features at a mid-range price.
#### Professional-Grade DAWs
1. **Pro Tools:** Often considered the industry standard in professional recording studios. It offers a comprehensive set of tools for recording, editing, mixing, and mastering.
2. **Ableton Live Suite:** Known for its intuitive workflow and powerful live performance capabilities. It's a top choice for electronic music producers and live performers.
3. **Cubase Pro:** Offers a suite of advanced features for recording, editing, mixing, and scoring, favored by professionals in music and film.
# Recording Environment
Source: https://docs.kits.ai/train/recording-environment
Avoid background noise, reverberant rooms, and audio bleed from headphones.
Your microphone can pick up a lot of unwanted noise that you might not notice right away. Listen for these common issues before you hit record.
## Background Noise
**Electrical Hum and Buzz**
Fluorescent lights, refrigerators, power lines, or improperly grounded equipment can cause a constant, low-frequency hum that can appear in your recording.
**Traffic and Outdoor Noises**
Take care to avoid sounds from outside like cars, planes, sirens, barking, or conversations. These noises are often difficult to remove in post-production and can easily disrupt the training or conversion process.
**Air Conditioning and Heating Systems**
HVAC systems can create a constant, ambient background noise. Their cycling on and off not only adds unwanted sound but also varies the noise floor, making consistency in recordings a challenge.
**Computer and Device Noise**
Don’t forget the hums and whirs of your own equipment. Computers, hard drives, and even LED lights can contribute to a noisy recording environment.
**Furniture and Accessory Movements**
Shuffling papers, creaking chairs, and jangling jewelry or keys can intrude unexpectedly into your recording.
## Room Reverberation
Hard, flat surfaces can cause sound reflections, leading to reverb or echo in your recordings. This can make your tracks sound hollow or distant, taking away from the intimacy or clarity you might be aiming for.
Clap your hands sharply in the room and listen. If you hear a flutter or a prolonged echo, you've got reverb issues.
Soft materials absorb sound. Carpets, rugs, or even thick curtains can dramatically reduce reflections. Cover hard floors, and if possible, hang curtains over windows and place fabric-covered furniture in the room.
Hard surfaces are a no-go. If you can't afford professional acoustic panels, consider using everyday items like canvas paintings, tapestries, or foam tiles to break up these surfaces.
Be mindful of where you place your microphone. Avoid recording too close to walls or in corners. Aim for the center of the room, or experiment with different placements to find the sweet spot with minimal reverb.
#### Pro Tip: Belting? Give yourself space
When belting, you might need more space: both in terms of distance from the mic and room size. Too much sound isolation (if you’re in a closet, booth, or if your microphone is surrounded with foam) can quickly lead to an overloaded mic capsule. When in doubt, opt for more room sound on belted phrases.
## Headphone Bleed
When recording, especially vocals, headphone audio can bleed into the microphone. This is common if the headphone volume is too high or if you’re using open-back headphones.
# Volume Level
Source: https://docs.kits.ai/train/volume-level
Optimize audio processing with Kits' volume level training guide.
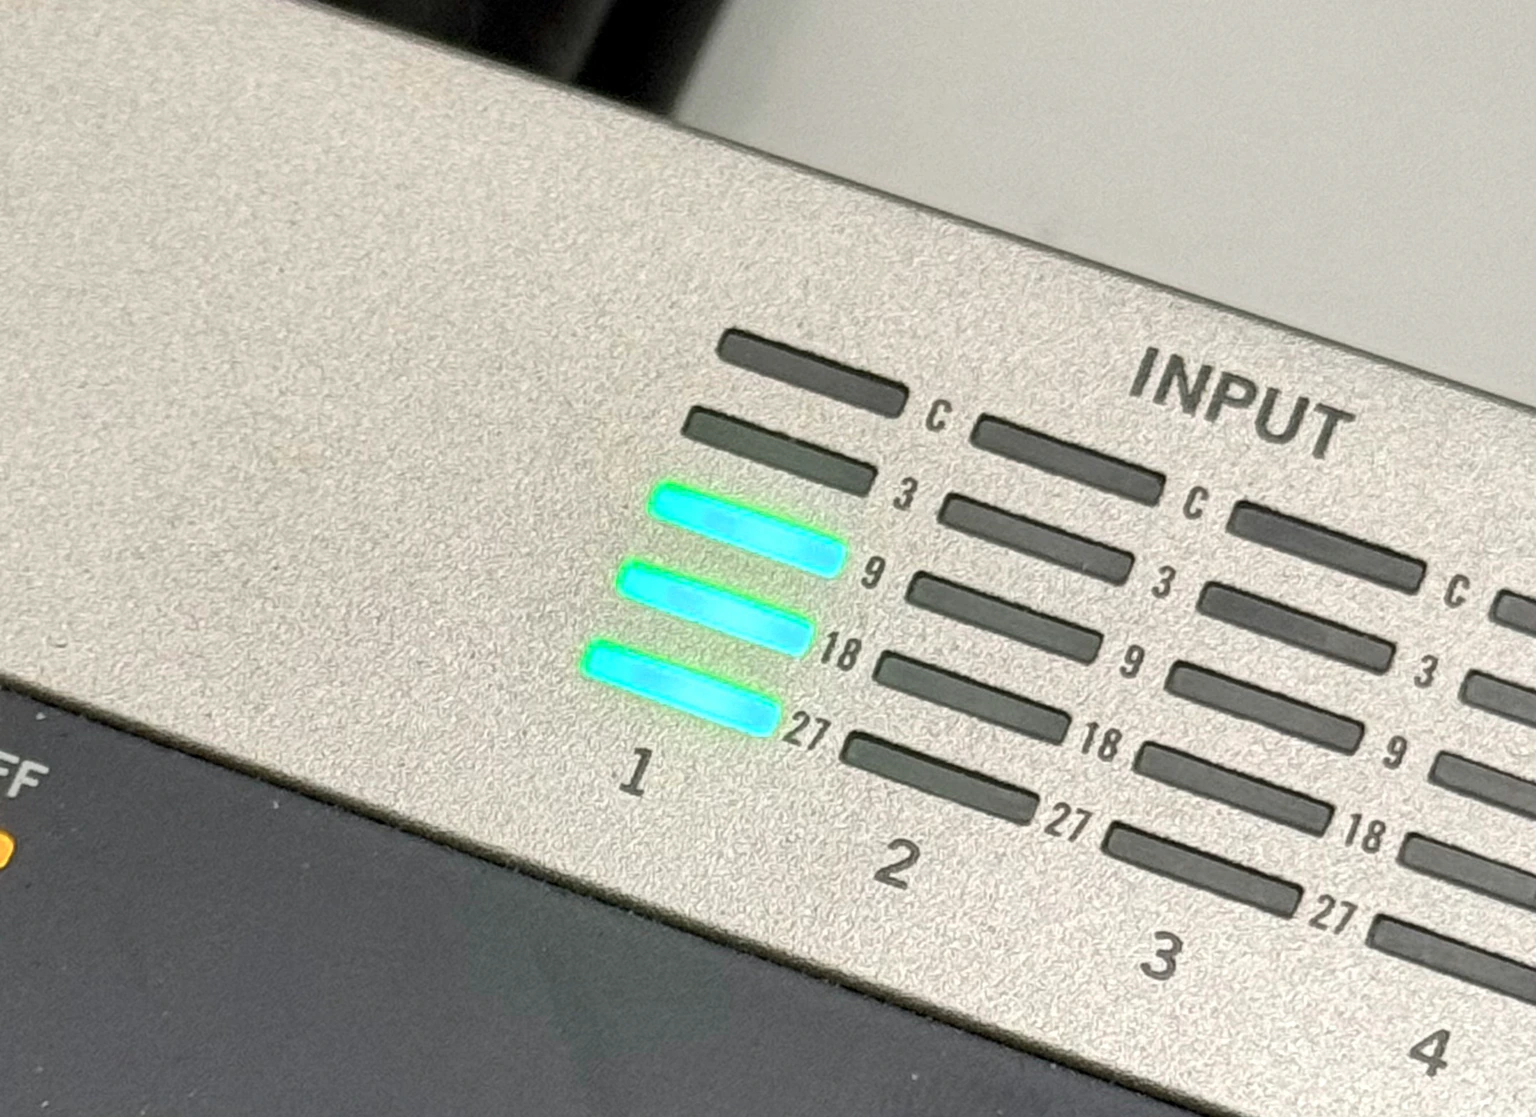 Start by speaking or singing at the loudest level you expect to reach during the performance. Watch the input level meters on your audio interface or recording software.
Make sure you stay around 30-50% of your meter. If you see yellow/red, turn it down. It's generally better to record too low than too loud.